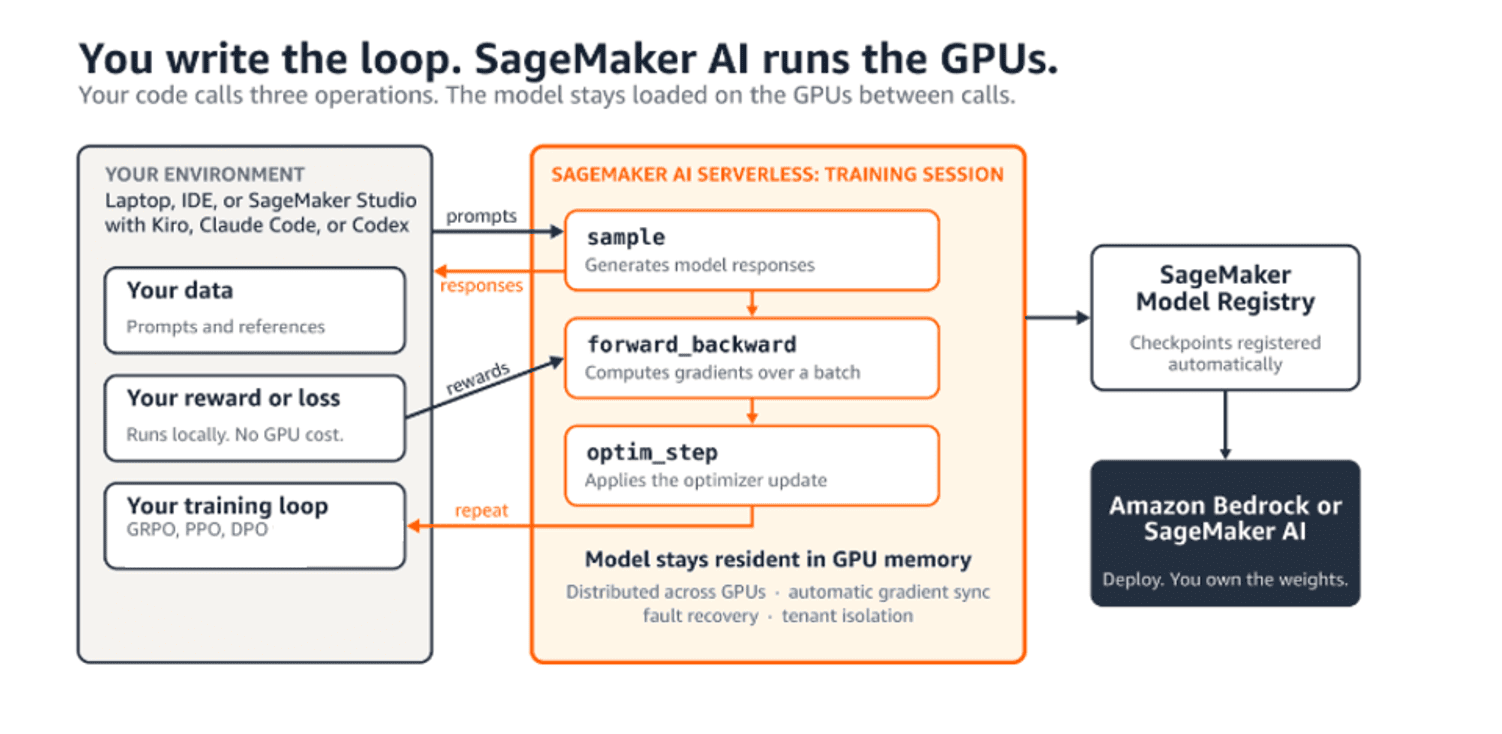
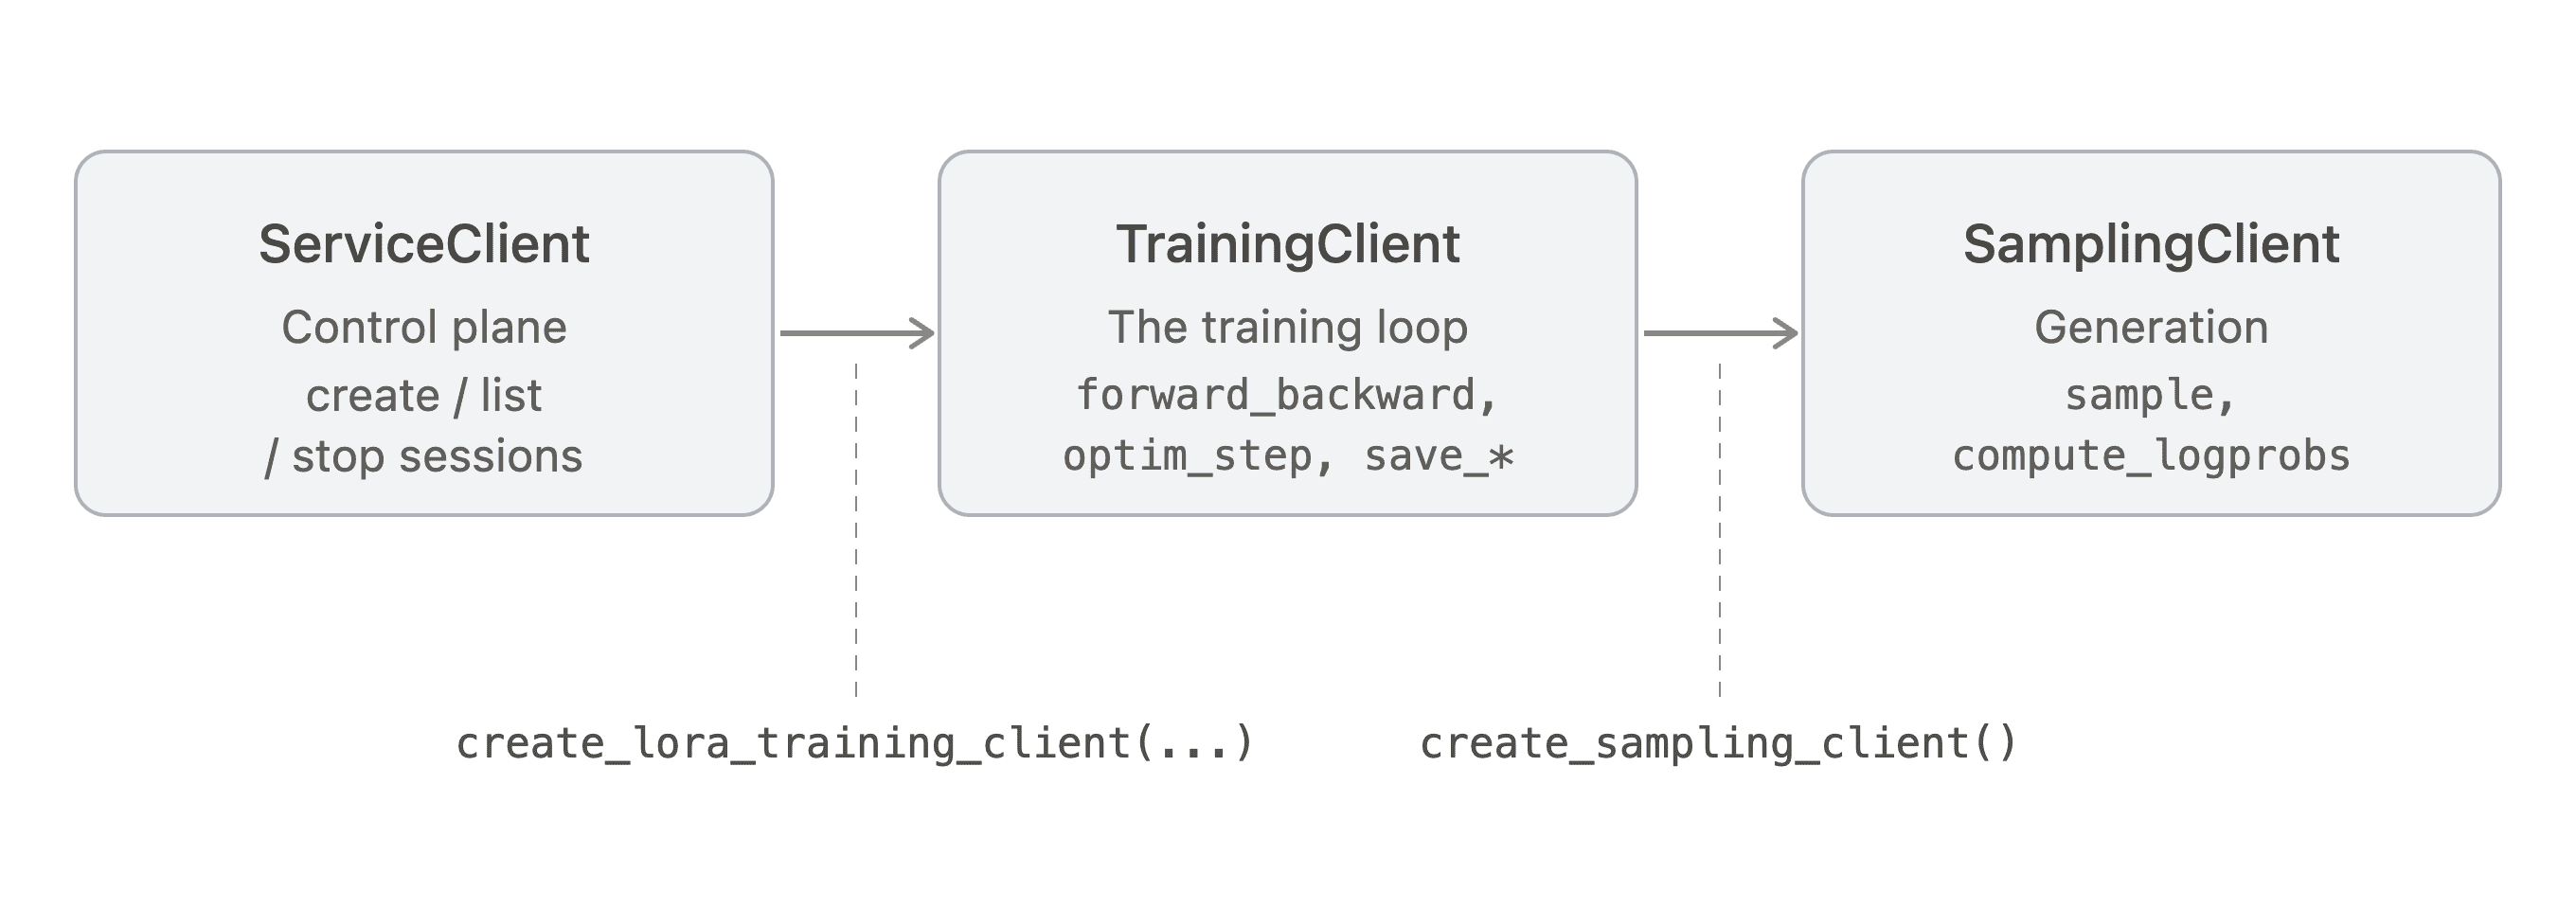
Favorite Fine-tuning a large language model (LLM) today usually forces a tradeoff between training loop control and operational simplicity. With fully managed services you select a base model, provide data and hyperparameters, and the service owns everything else, which works well when a standard, prepackaged recipe fits your problem. Less
Read More
 Shared by AWS Machine Learning October 22, 2026
Favorite Companies getting real results from AI aren’t only using foundation models (FMs) off the shelf. They’re customizing open-weight models using post-training techniques such as reinforcement learning. A model trained on your business context, product catalog, or clinical vocabulary will be more accurate for your task and cost less to
Read More
Shared by AWS Machine Learning October 22, 2026
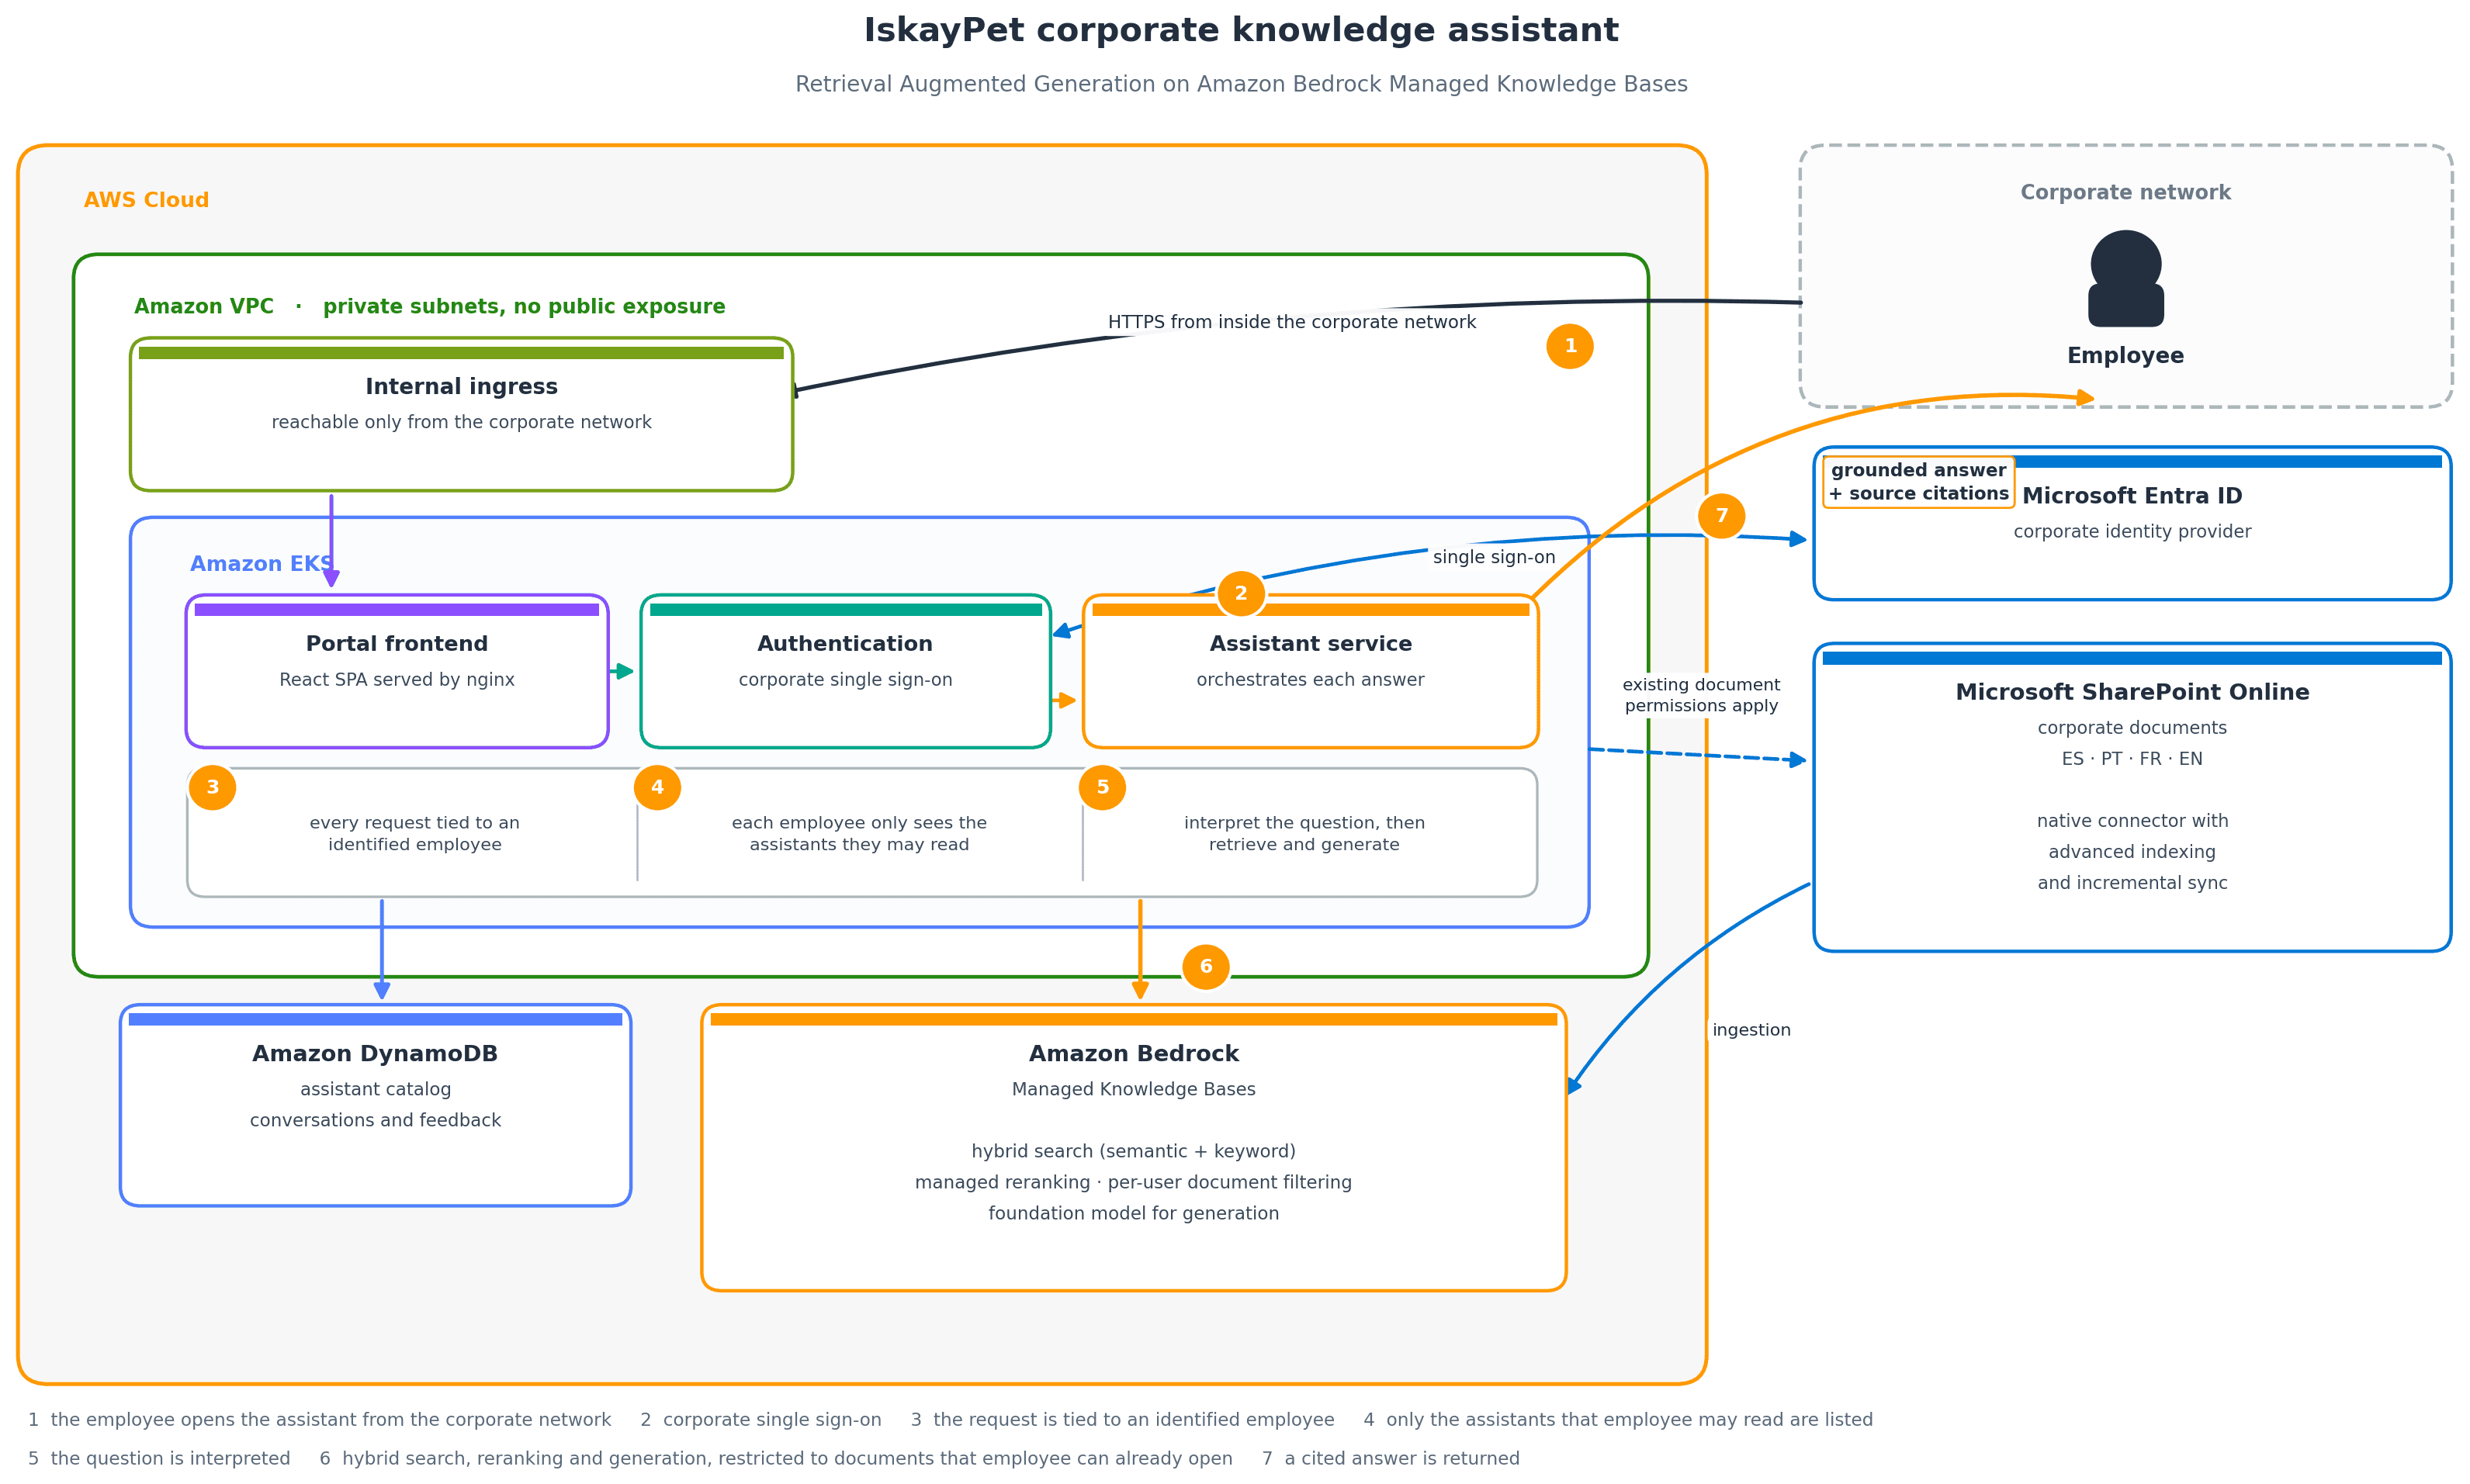
Favorite IskayPet’s office teams had a knowledge challenge. Answers to everyday operational questions, such as a return policy, a veterinary protocol, or an onboarding step, lived in hundreds of Microsoft SharePoint documents spread across four languages and three countries. Finding the right information in large document repositories took a long
Read More
Shared by AWS Machine Learning October 22, 2026
Favorite Amazon Polly Generative engine now offers more natural and accurate speech output. We’re introducing an upgrade to the Amazon Polly Generative engine that delivers more expressive, more accurate speech output with low latency. The upgrade adds 14 new voices across 9 locales, including general availability of Generative voices in
Read More
Shared by AWS Machine Learning October 22, 2026
Favorite Most large language models (LLMs) use transformer architectures with softmax attention. During inference, their key-value (KV) cache grows with the conversation or document context. This can reduce concurrency, increase serving cost, and force agentic applications to discard useful history. i14 designed Laplace 3B as a linear attention alternative. Its
Read More
Shared by AWS Machine Learning October 21, 2026
Favorite For U.S. Hunger, feeding families takes more than delivering food to them. It takes understanding the people behind each request, the pressures they face, and the business that makes the mission possible. That means connecting information across the organization. Its mission is to feed families today and unite them
Read More
Shared by AWS Machine Learning October 21, 2026
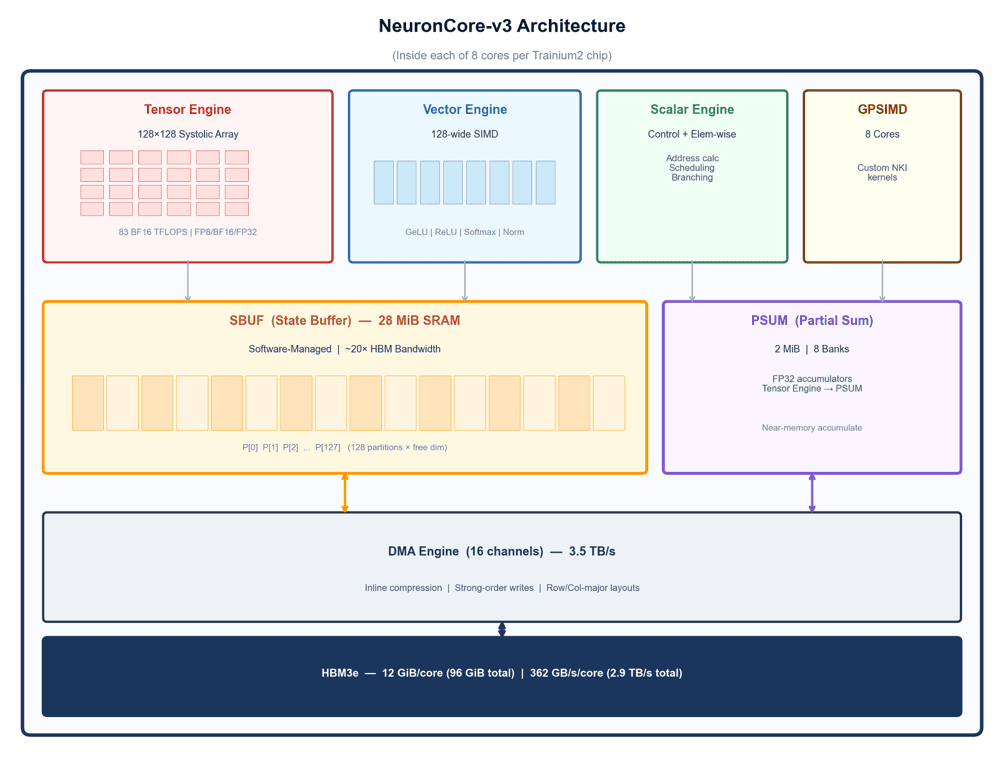
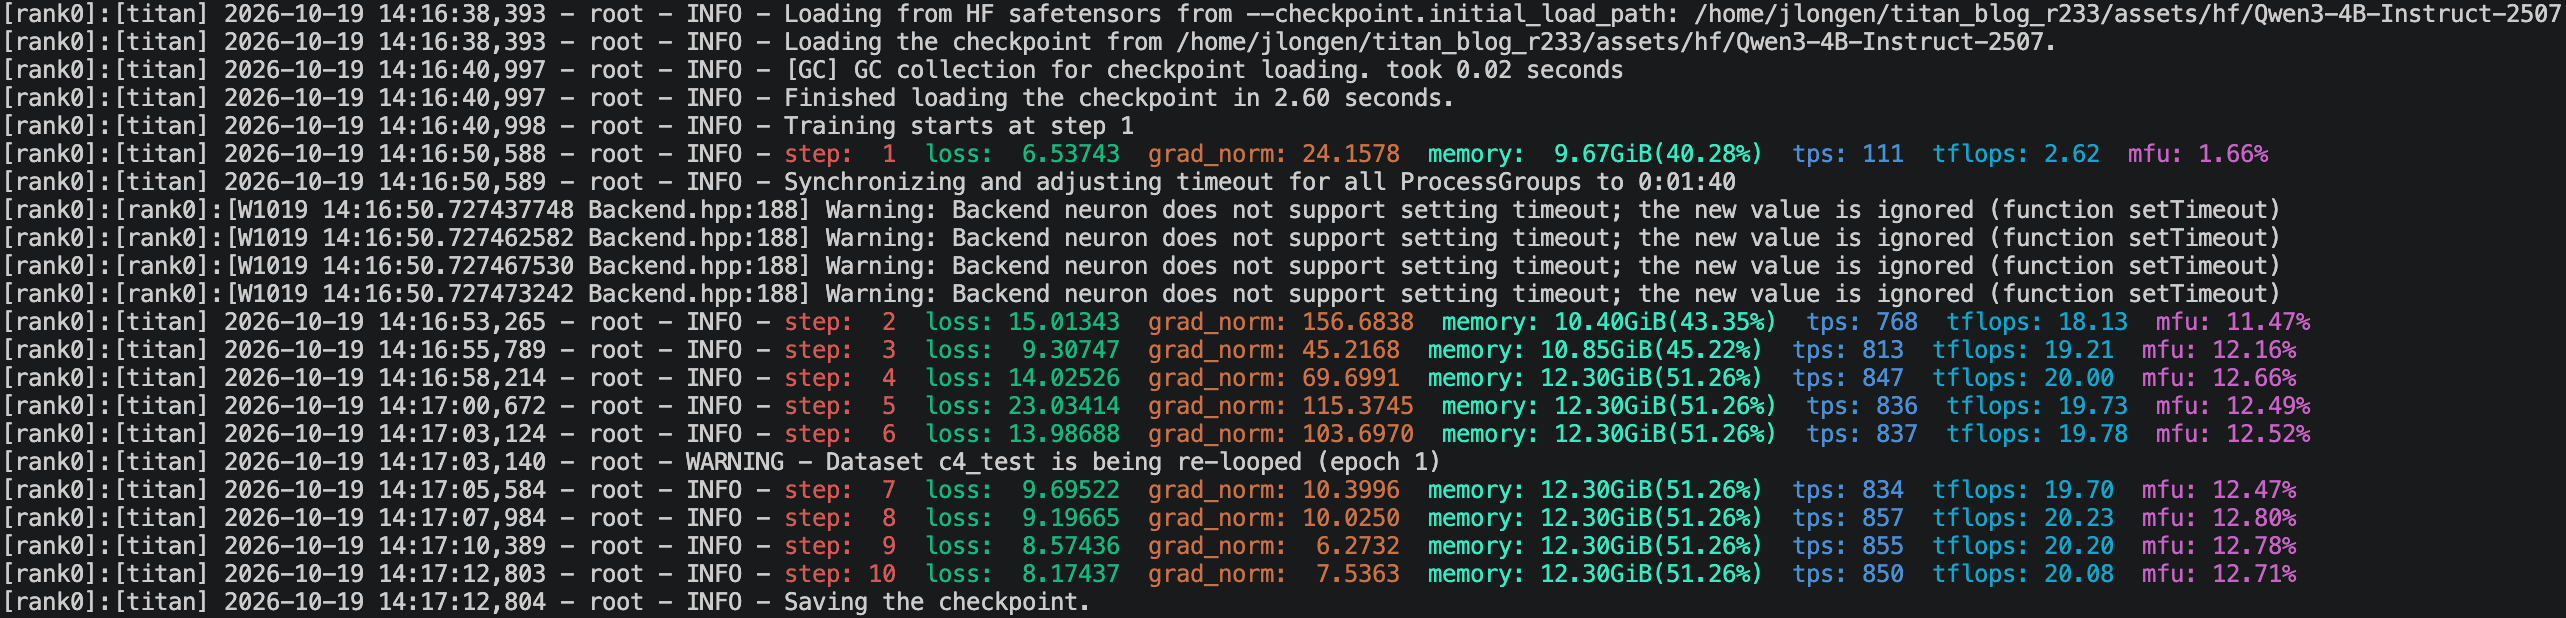
Favorite Using torchtitan on AWS Trainium means using it the way you always have. TorchNeuron registers Trainium as a native PyTorch device, which lets torchtitan use it through standard PyTorch interfaces. You can use these configurations to pre-train from random initialization or fine-tune published weights. You can also customize the
Read More
Shared by AWS Machine Learning October 21, 2026
Favorite Widespread AI adoption is propelling Southeast Asia’s digital economy to a projected $368 billion in 2026 and $1 trillion by 2035. View Original Source (blog.google/technology/ai/) Here.
Favorite Amazon SageMaker JumpStart is a machine learning (ML) hub within Amazon SageMaker AI that provides access to a curated catalog of AI models, solution templates, and example notebooks. It reduces the time it takes to go from model selection to deployment. You can use it to evaluate open source
Read More
Shared by AWS Machine Learning October 20, 2026
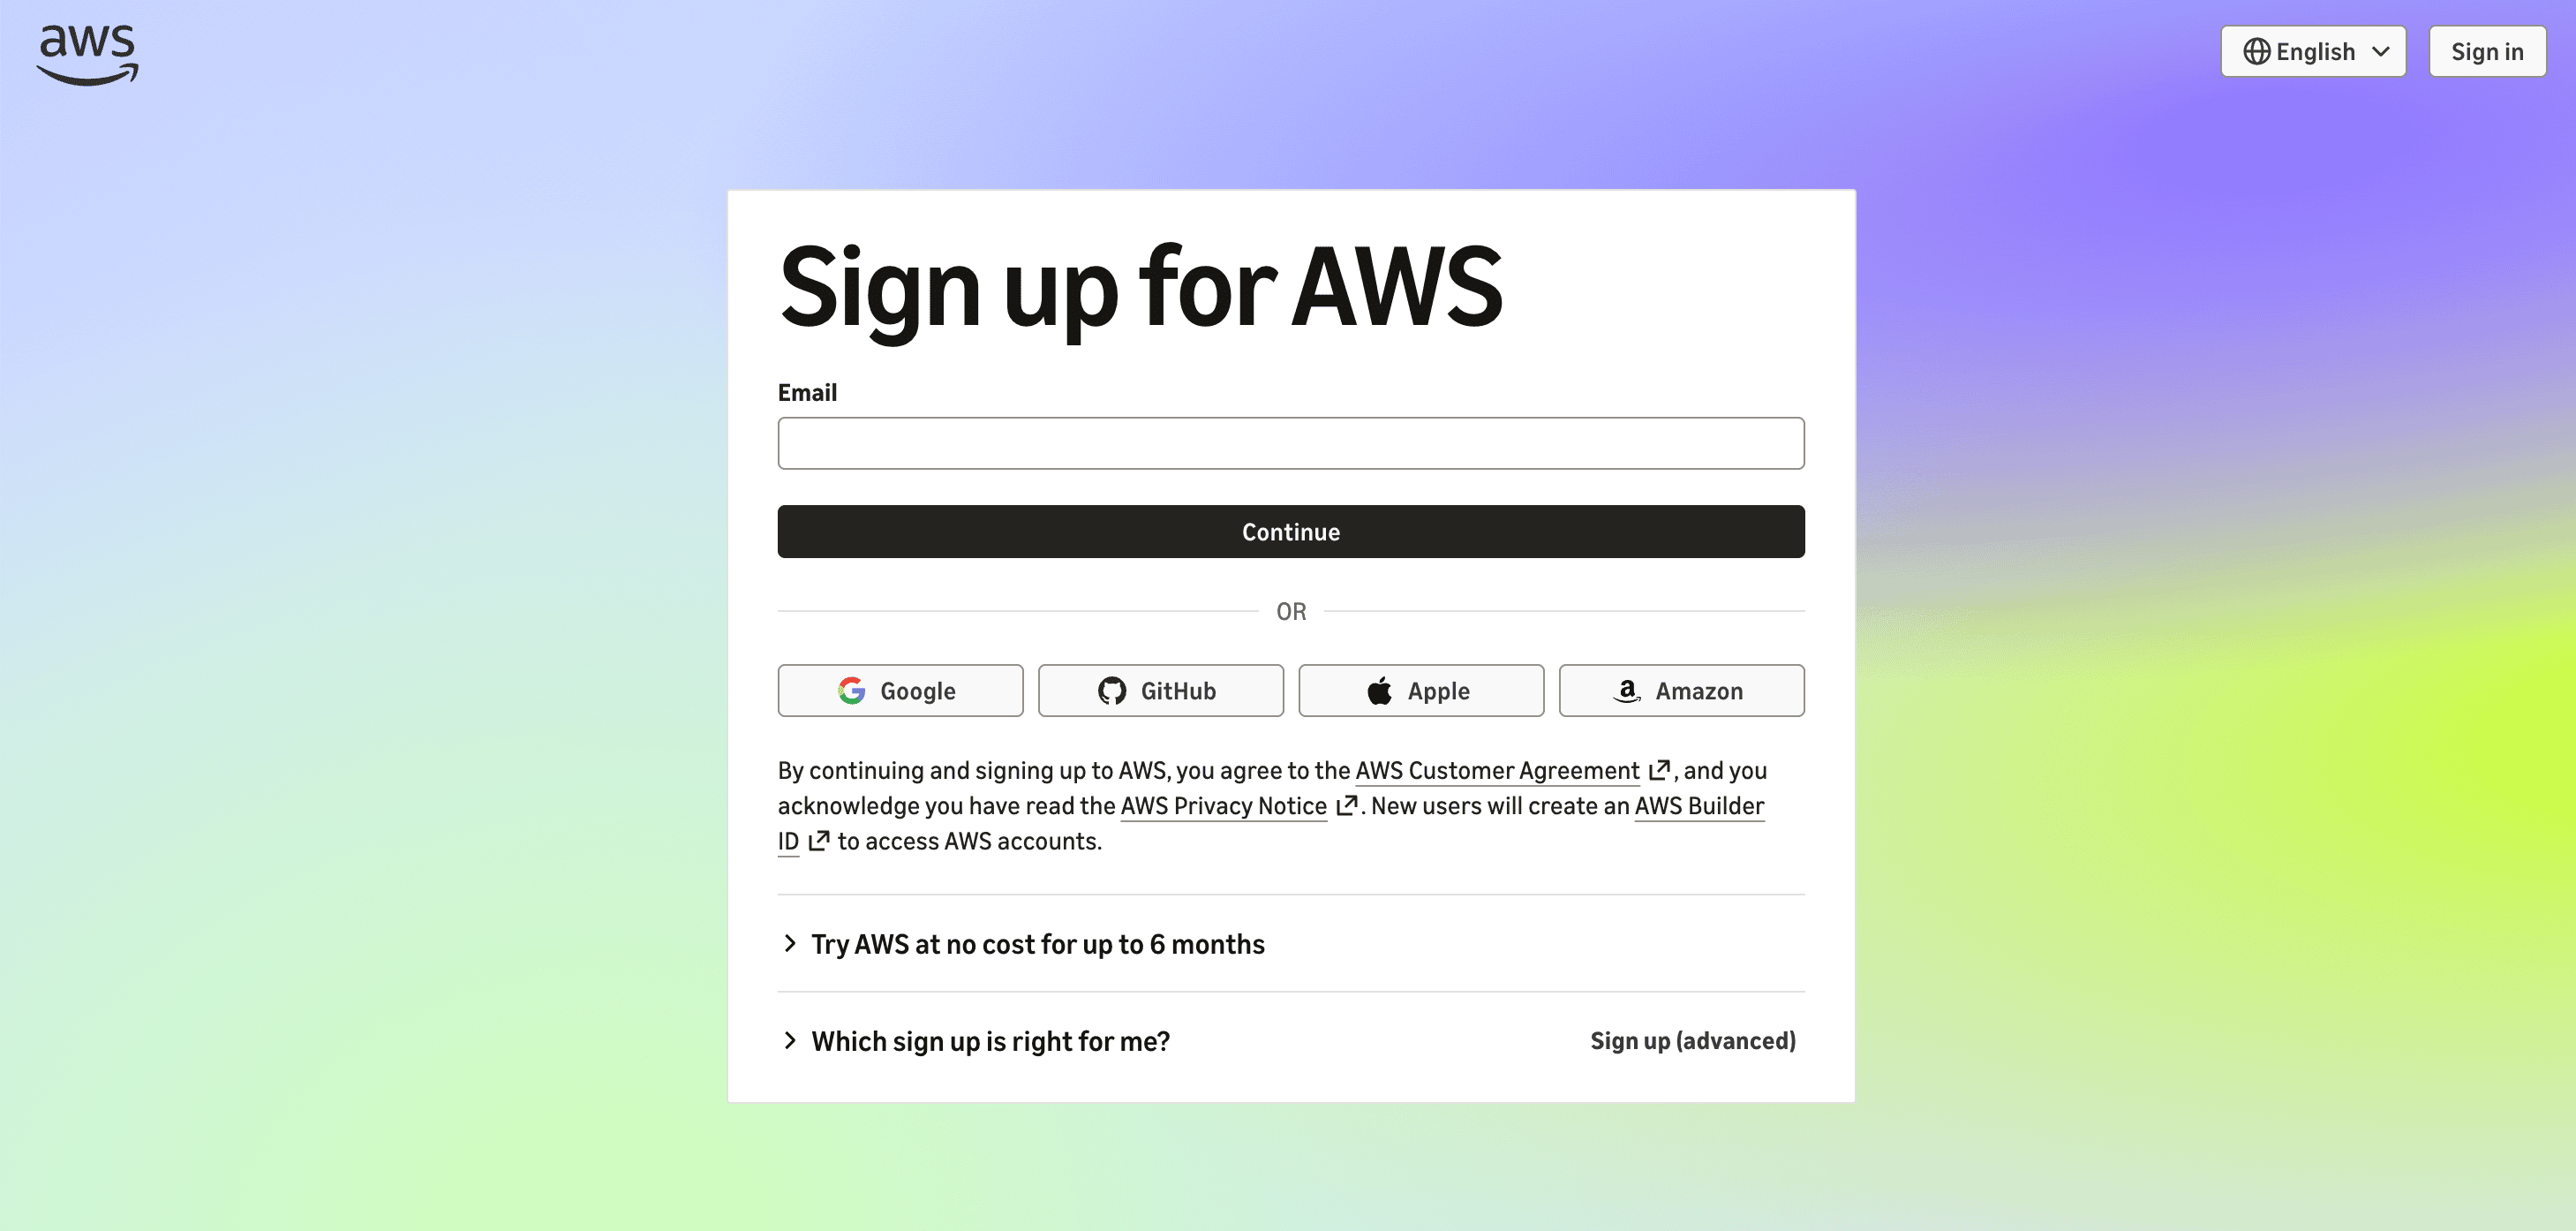
Favorite Today, we’re excited to announce that new Amazon SageMaker AI customers can now land inside a fully configured Amazon SageMaker Studio environment in only a few steps after signing up for AWS. You can use a sign-in method that you already have, such as Amazon, Apple, GitHub, Google, or
Read More
Shared by AWS Machine Learning October 20, 2026
 Shared by AWS Machine Learning October 22, 2026