Favorite Most large language models (LLMs) use transformer architectures with softmax attention. During inference, their key-value (KV) cache grows with the conversation or document context. This can reduce concurrency, increase serving cost, and force agentic applications to discard useful history. i14 designed Laplace 3B as a linear attention alternative. Its
Read More
 Shared by AWS Machine Learning October 21, 2026
Favorite For U.S. Hunger, feeding families takes more than delivering food to them. It takes understanding the people behind each request, the pressures they face, and the business that makes the mission possible. That means connecting information across the organization. Its mission is to feed families today and unite them
Read More
Shared by AWS Machine Learning October 21, 2026
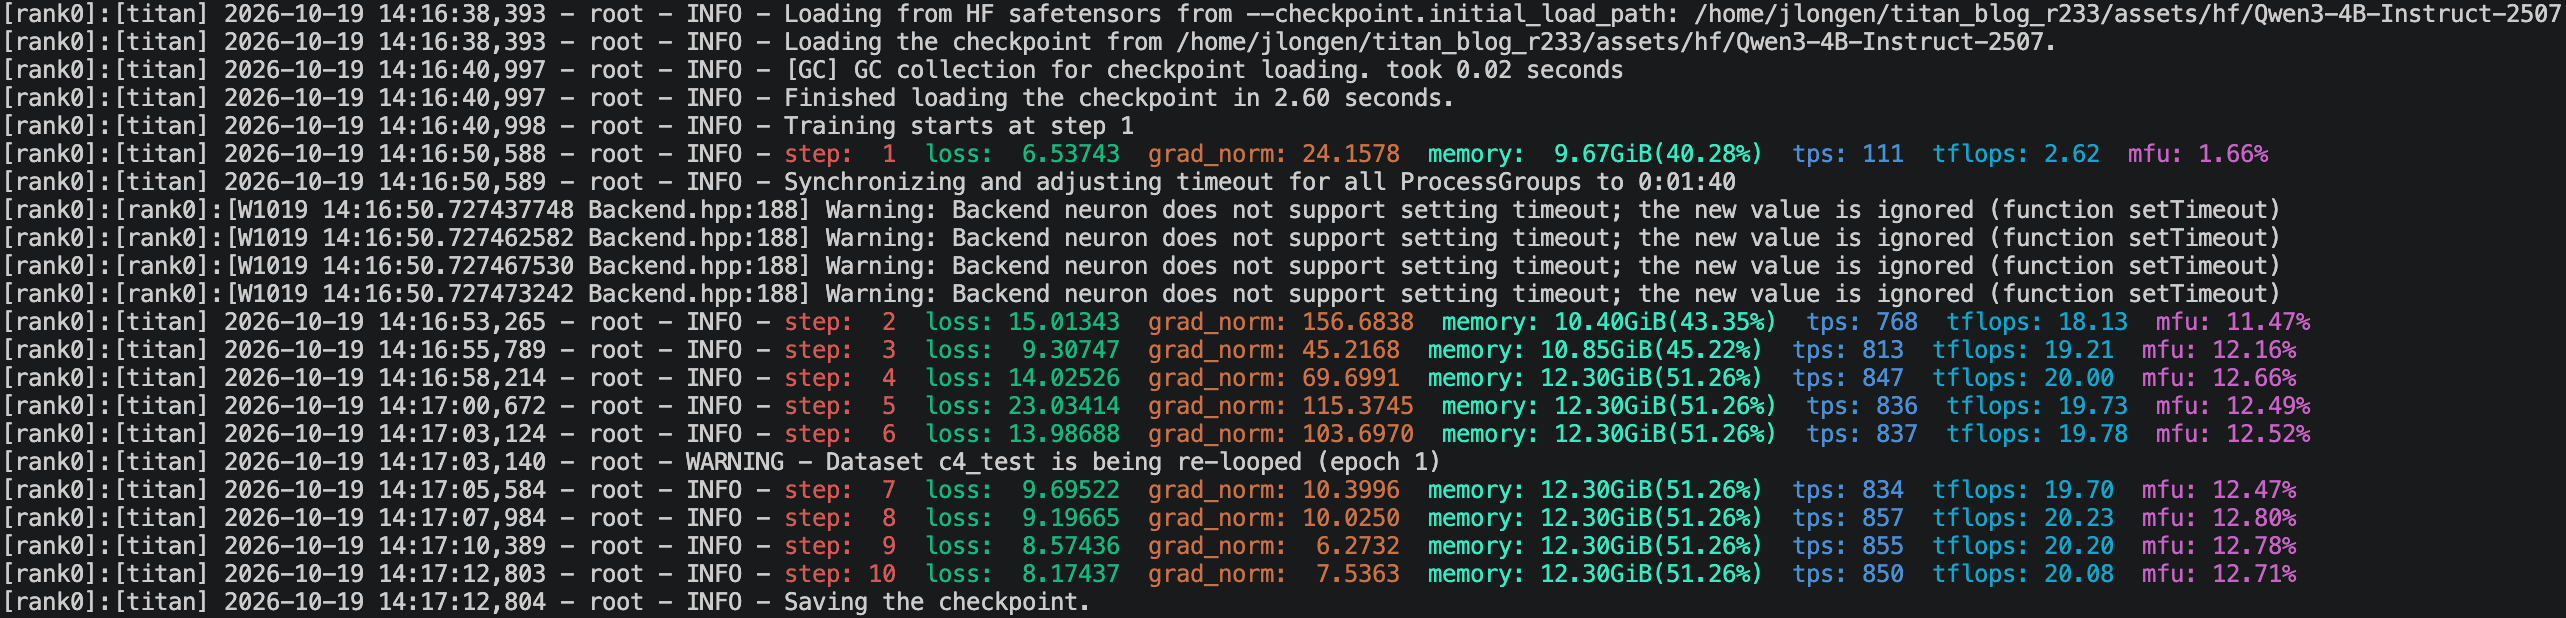
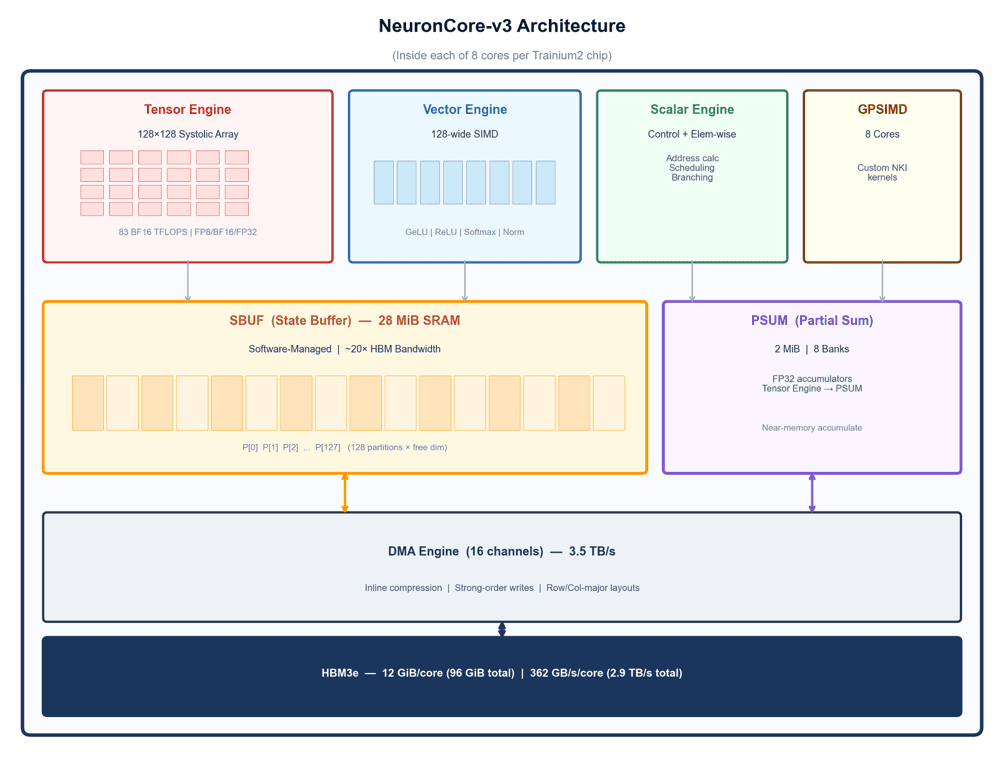
Favorite Using torchtitan on AWS Trainium means using it the way you always have. TorchNeuron registers Trainium as a native PyTorch device, which lets torchtitan use it through standard PyTorch interfaces. You can use these configurations to pre-train from random initialization or fine-tune published weights. You can also customize the
Read More
Shared by AWS Machine Learning October 21, 2026
Favorite Widespread AI adoption is propelling Southeast Asia’s digital economy to a projected $368 billion in 2026 and $1 trillion by 2035. View Original Source (blog.google/technology/ai/) Here.
Favorite Amazon SageMaker JumpStart is a machine learning (ML) hub within Amazon SageMaker AI that provides access to a curated catalog of AI models, solution templates, and example notebooks. It reduces the time it takes to go from model selection to deployment. You can use it to evaluate open source
Read More
Shared by AWS Machine Learning October 20, 2026
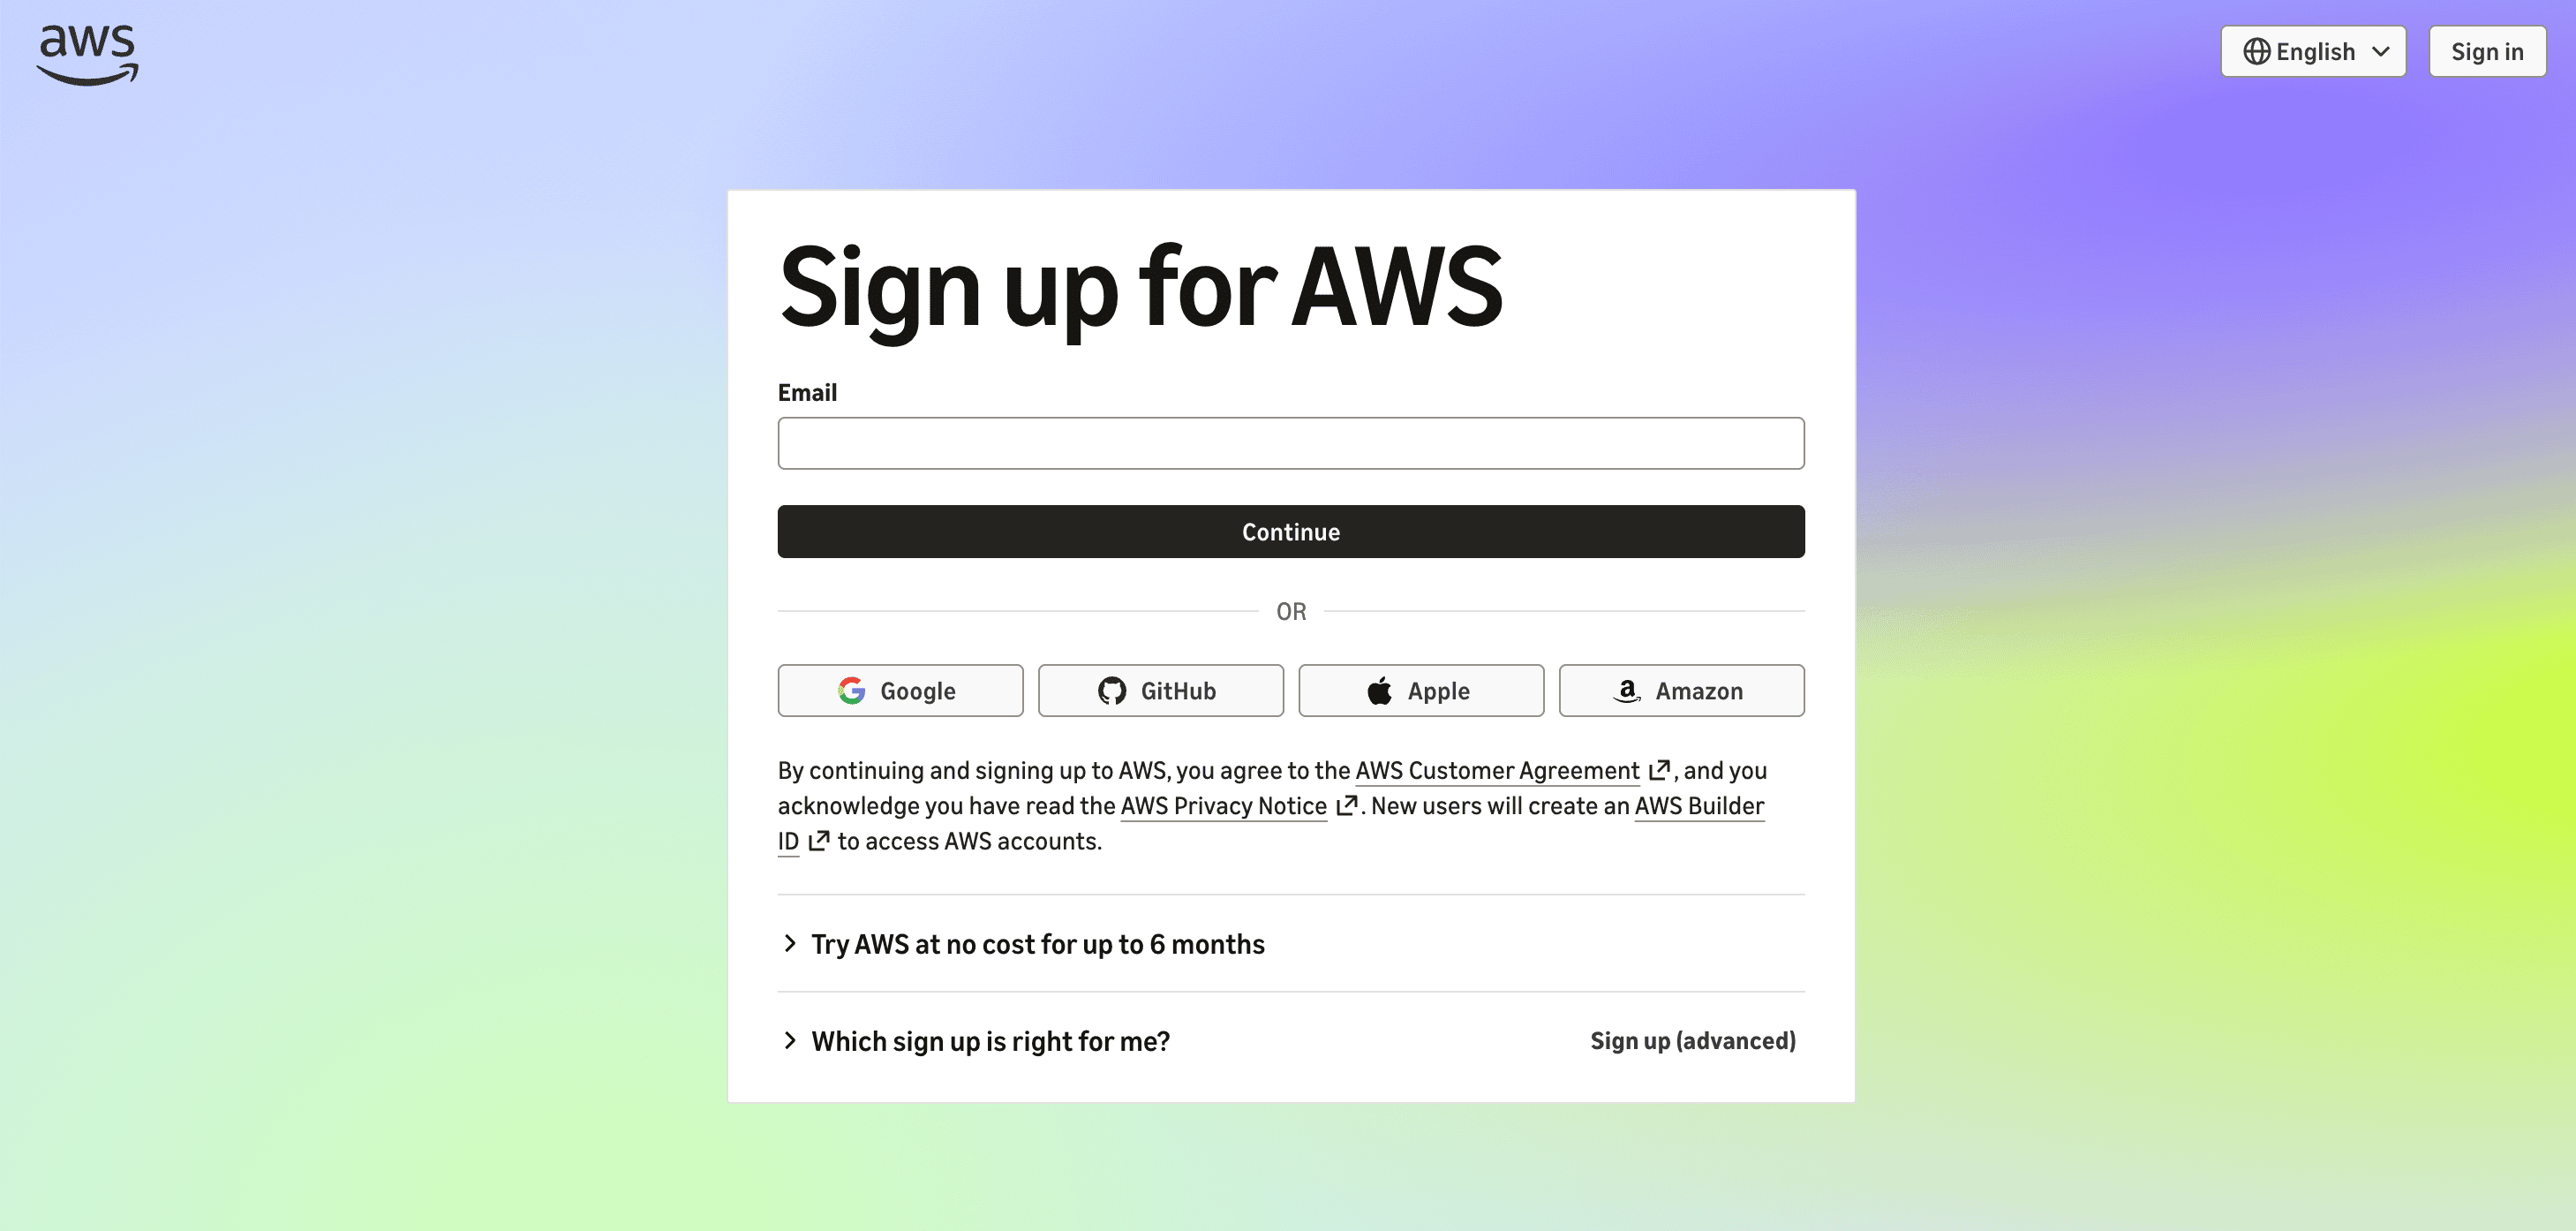
Favorite Today, we’re excited to announce that new Amazon SageMaker AI customers can now land inside a fully configured Amazon SageMaker Studio environment in only a few steps after signing up for AWS. You can use a sign-in method that you already have, such as Amazon, Apple, GitHub, Google, or
Read More
Shared by AWS Machine Learning October 20, 2026
Favorite Amazon Bedrock now supports structured outputs for all Anthropic Claude models, on both the bedrock-runtime and bedrock-mantle endpoints, where the model is available. Whether you call Claude through Boto3 and the bedrock-runtime APIs or through the Messages API and the bedrock-mantle endpoint, you can now receive schema-compliant JSON responses
Read More
Shared by AWS Machine Learning October 20, 2026
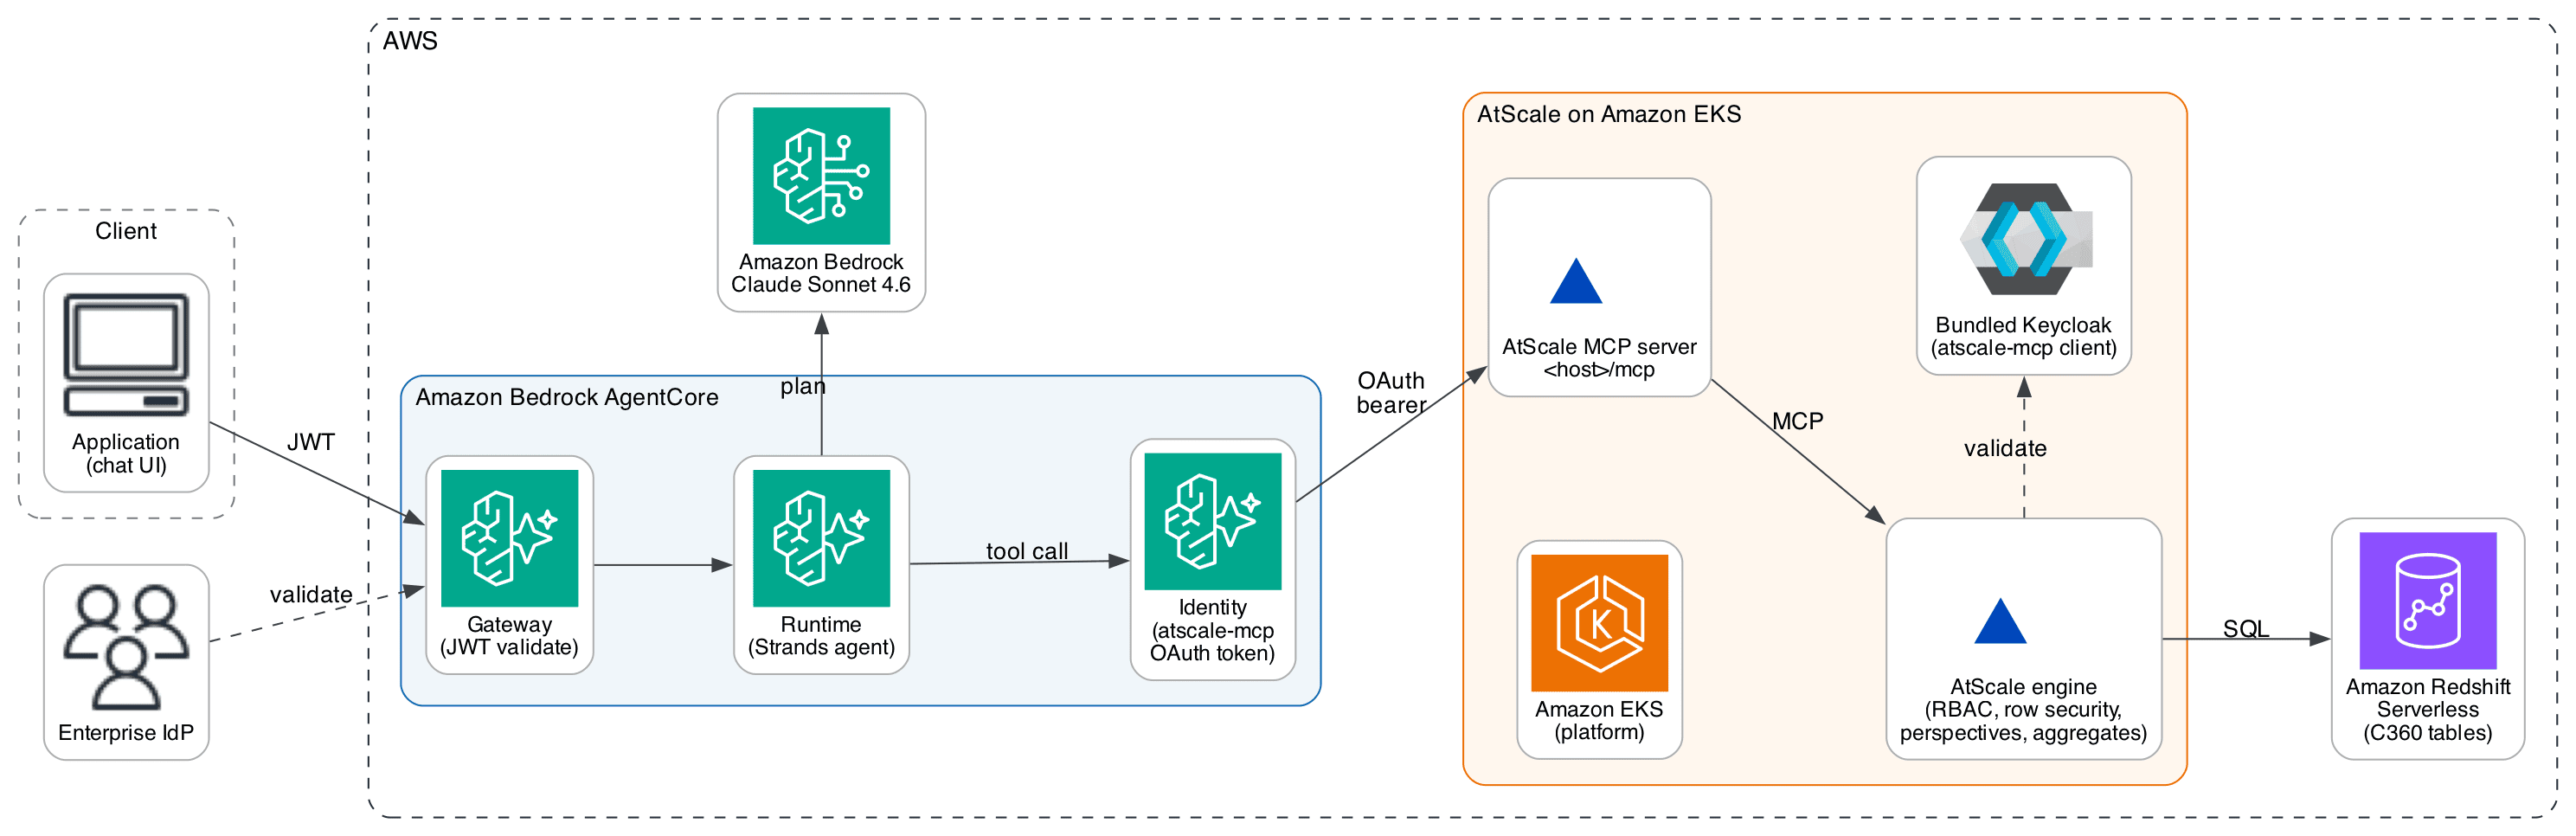
Favorite In the first post in this series, we built a semantic layer on AWS using Stardog’s knowledge graph over Amazon Aurora and Amazon Redshift. We ran a Strands agent on Amazon Bedrock AgentCore against that layer. The second post kept the same customer 360 (C360) pattern and swapped in
Read More
Shared by AWS Machine Learning October 20, 2026
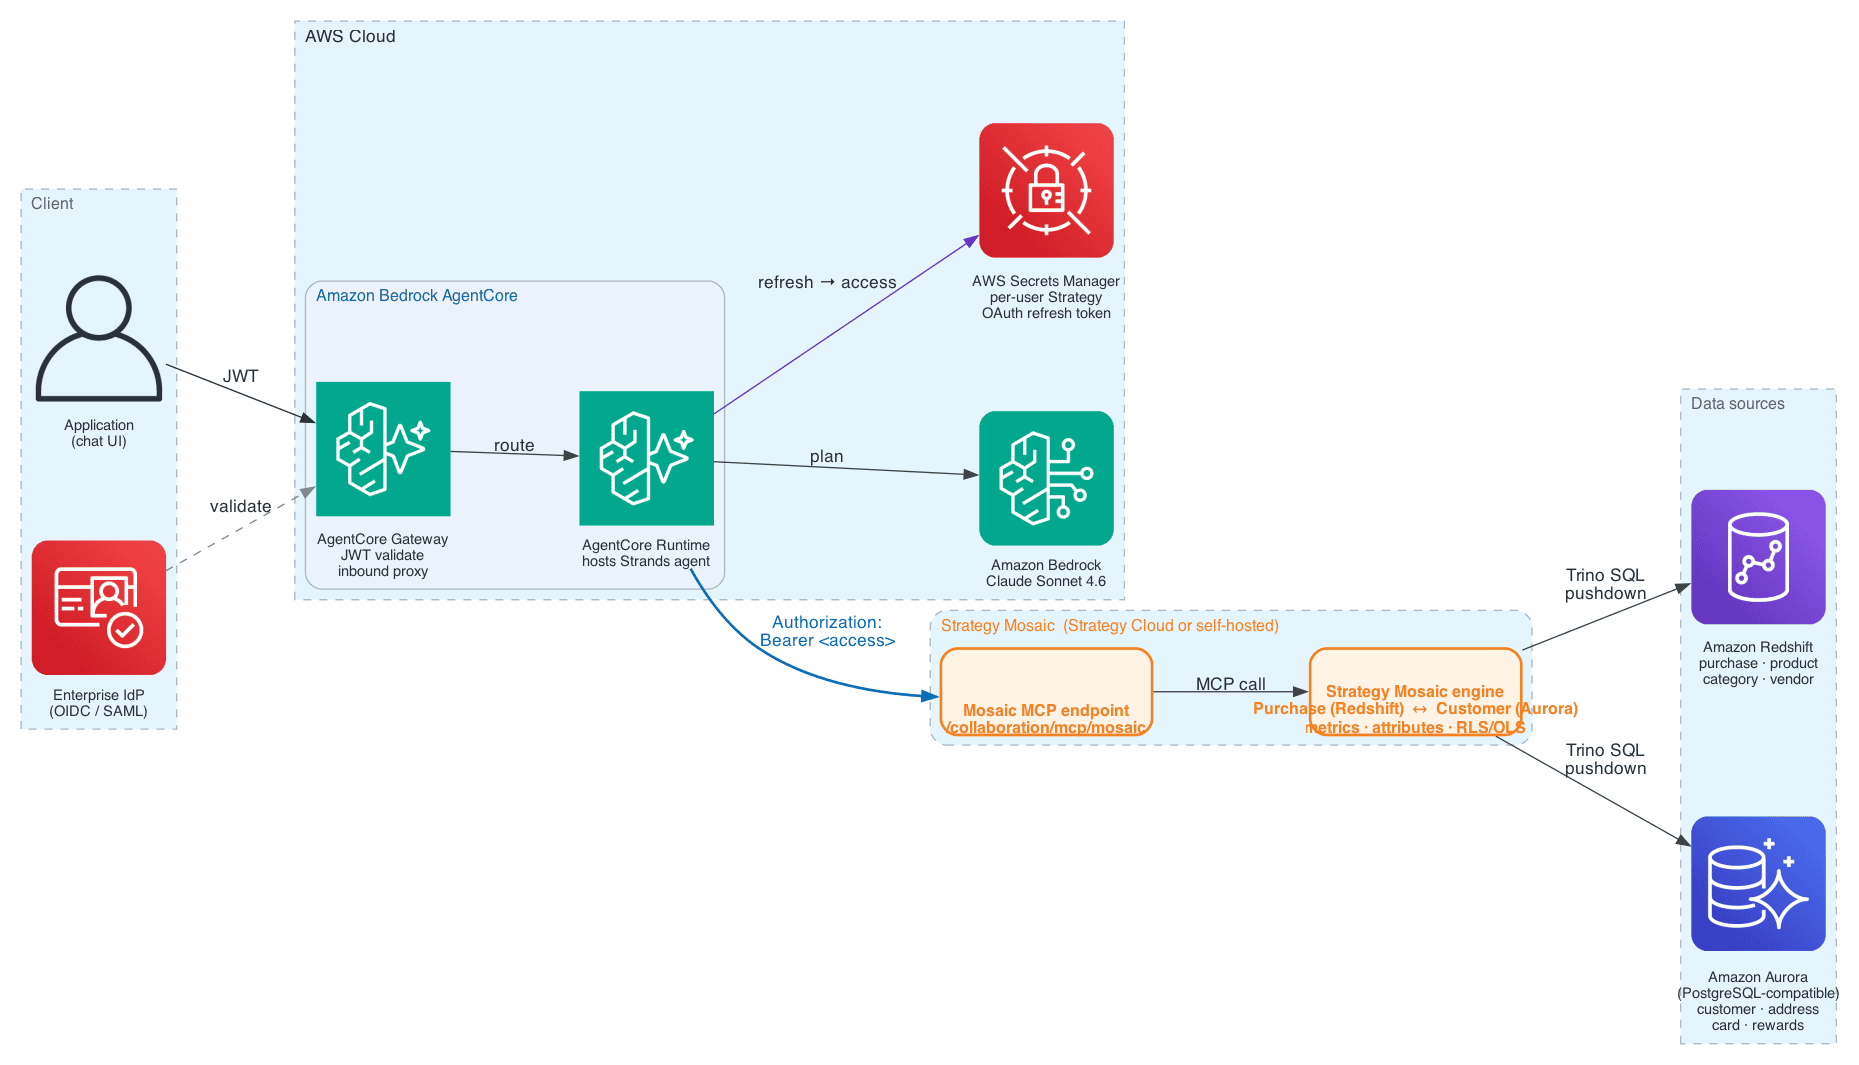
Favorite This post is co-written with Zhili Cheng, Principal Product Manager, George Earle, Director, AI Engineering, and Kyler K, Sales Engineer of Strategy. In the first post in this series, we built a semantic layer on AWS using Stardog’s knowledge graph over Amazon Aurora and Amazon Redshift and ran a
Read More
Shared by AWS Machine Learning October 20, 2026
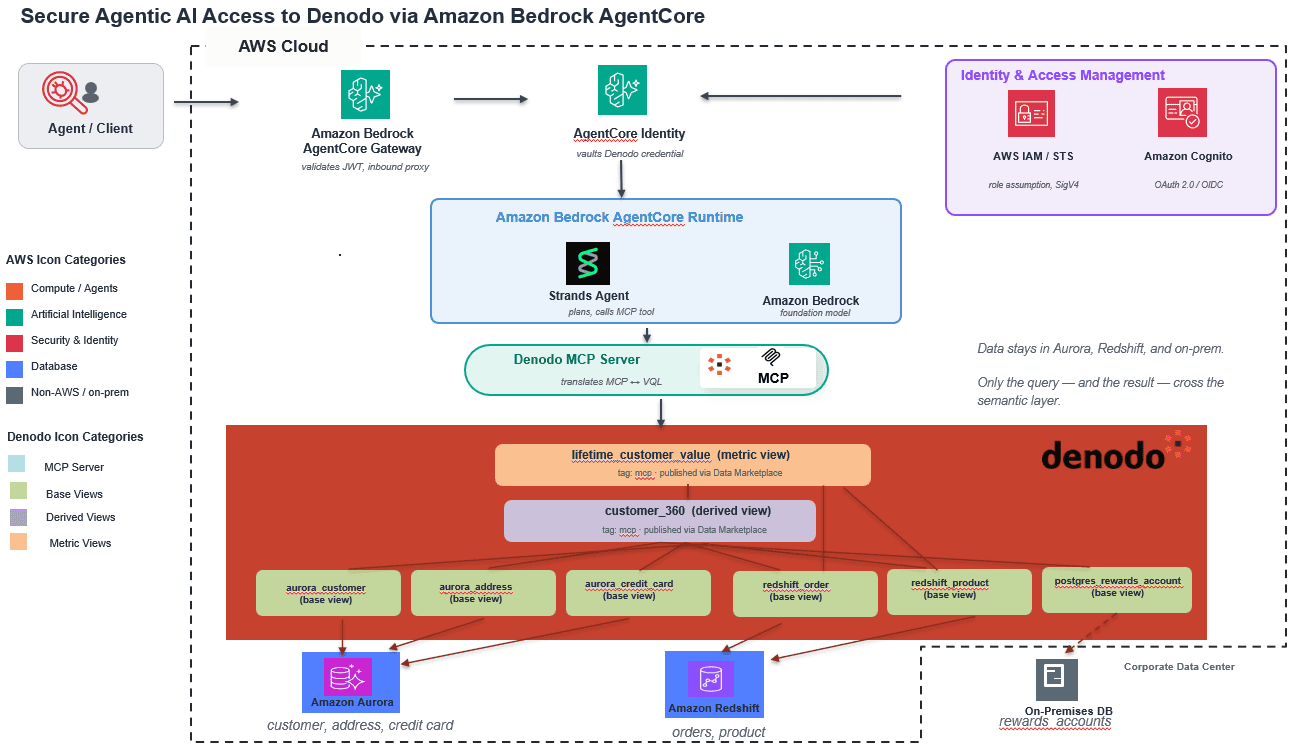
Favorite Agentic AI applications need governed access to live enterprise data. That data can live in operational systems, analytical warehouses, SaaS applications, other clouds, or on premises. In the previous post in this series, we built a semantic layer on AWS using Stardog’s knowledge graph over Amazon Aurora and Amazon
Read More
Shared by AWS Machine Learning October 20, 2026
 Shared by AWS Machine Learning October 21, 2026