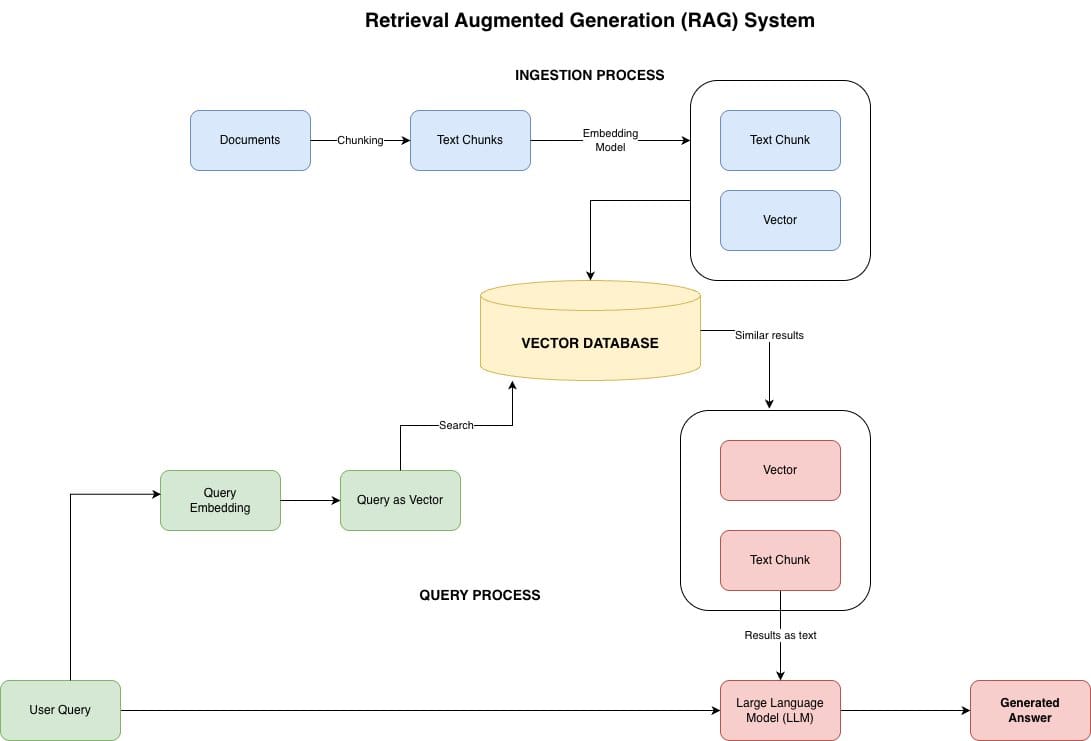
Favorite When building a Retrieval Augmented Generation (RAG) solution with Amazon Bedrock Knowledge Bases, selecting the right vector store impacts performance and cost. Amazon Bedrock Knowledge Bases offers a fully managed option and a customer-managed option where you choose your own vector store. This post focuses on the customer-managed path,
Read More
 Shared by AWS Machine Learning September 18, 2026
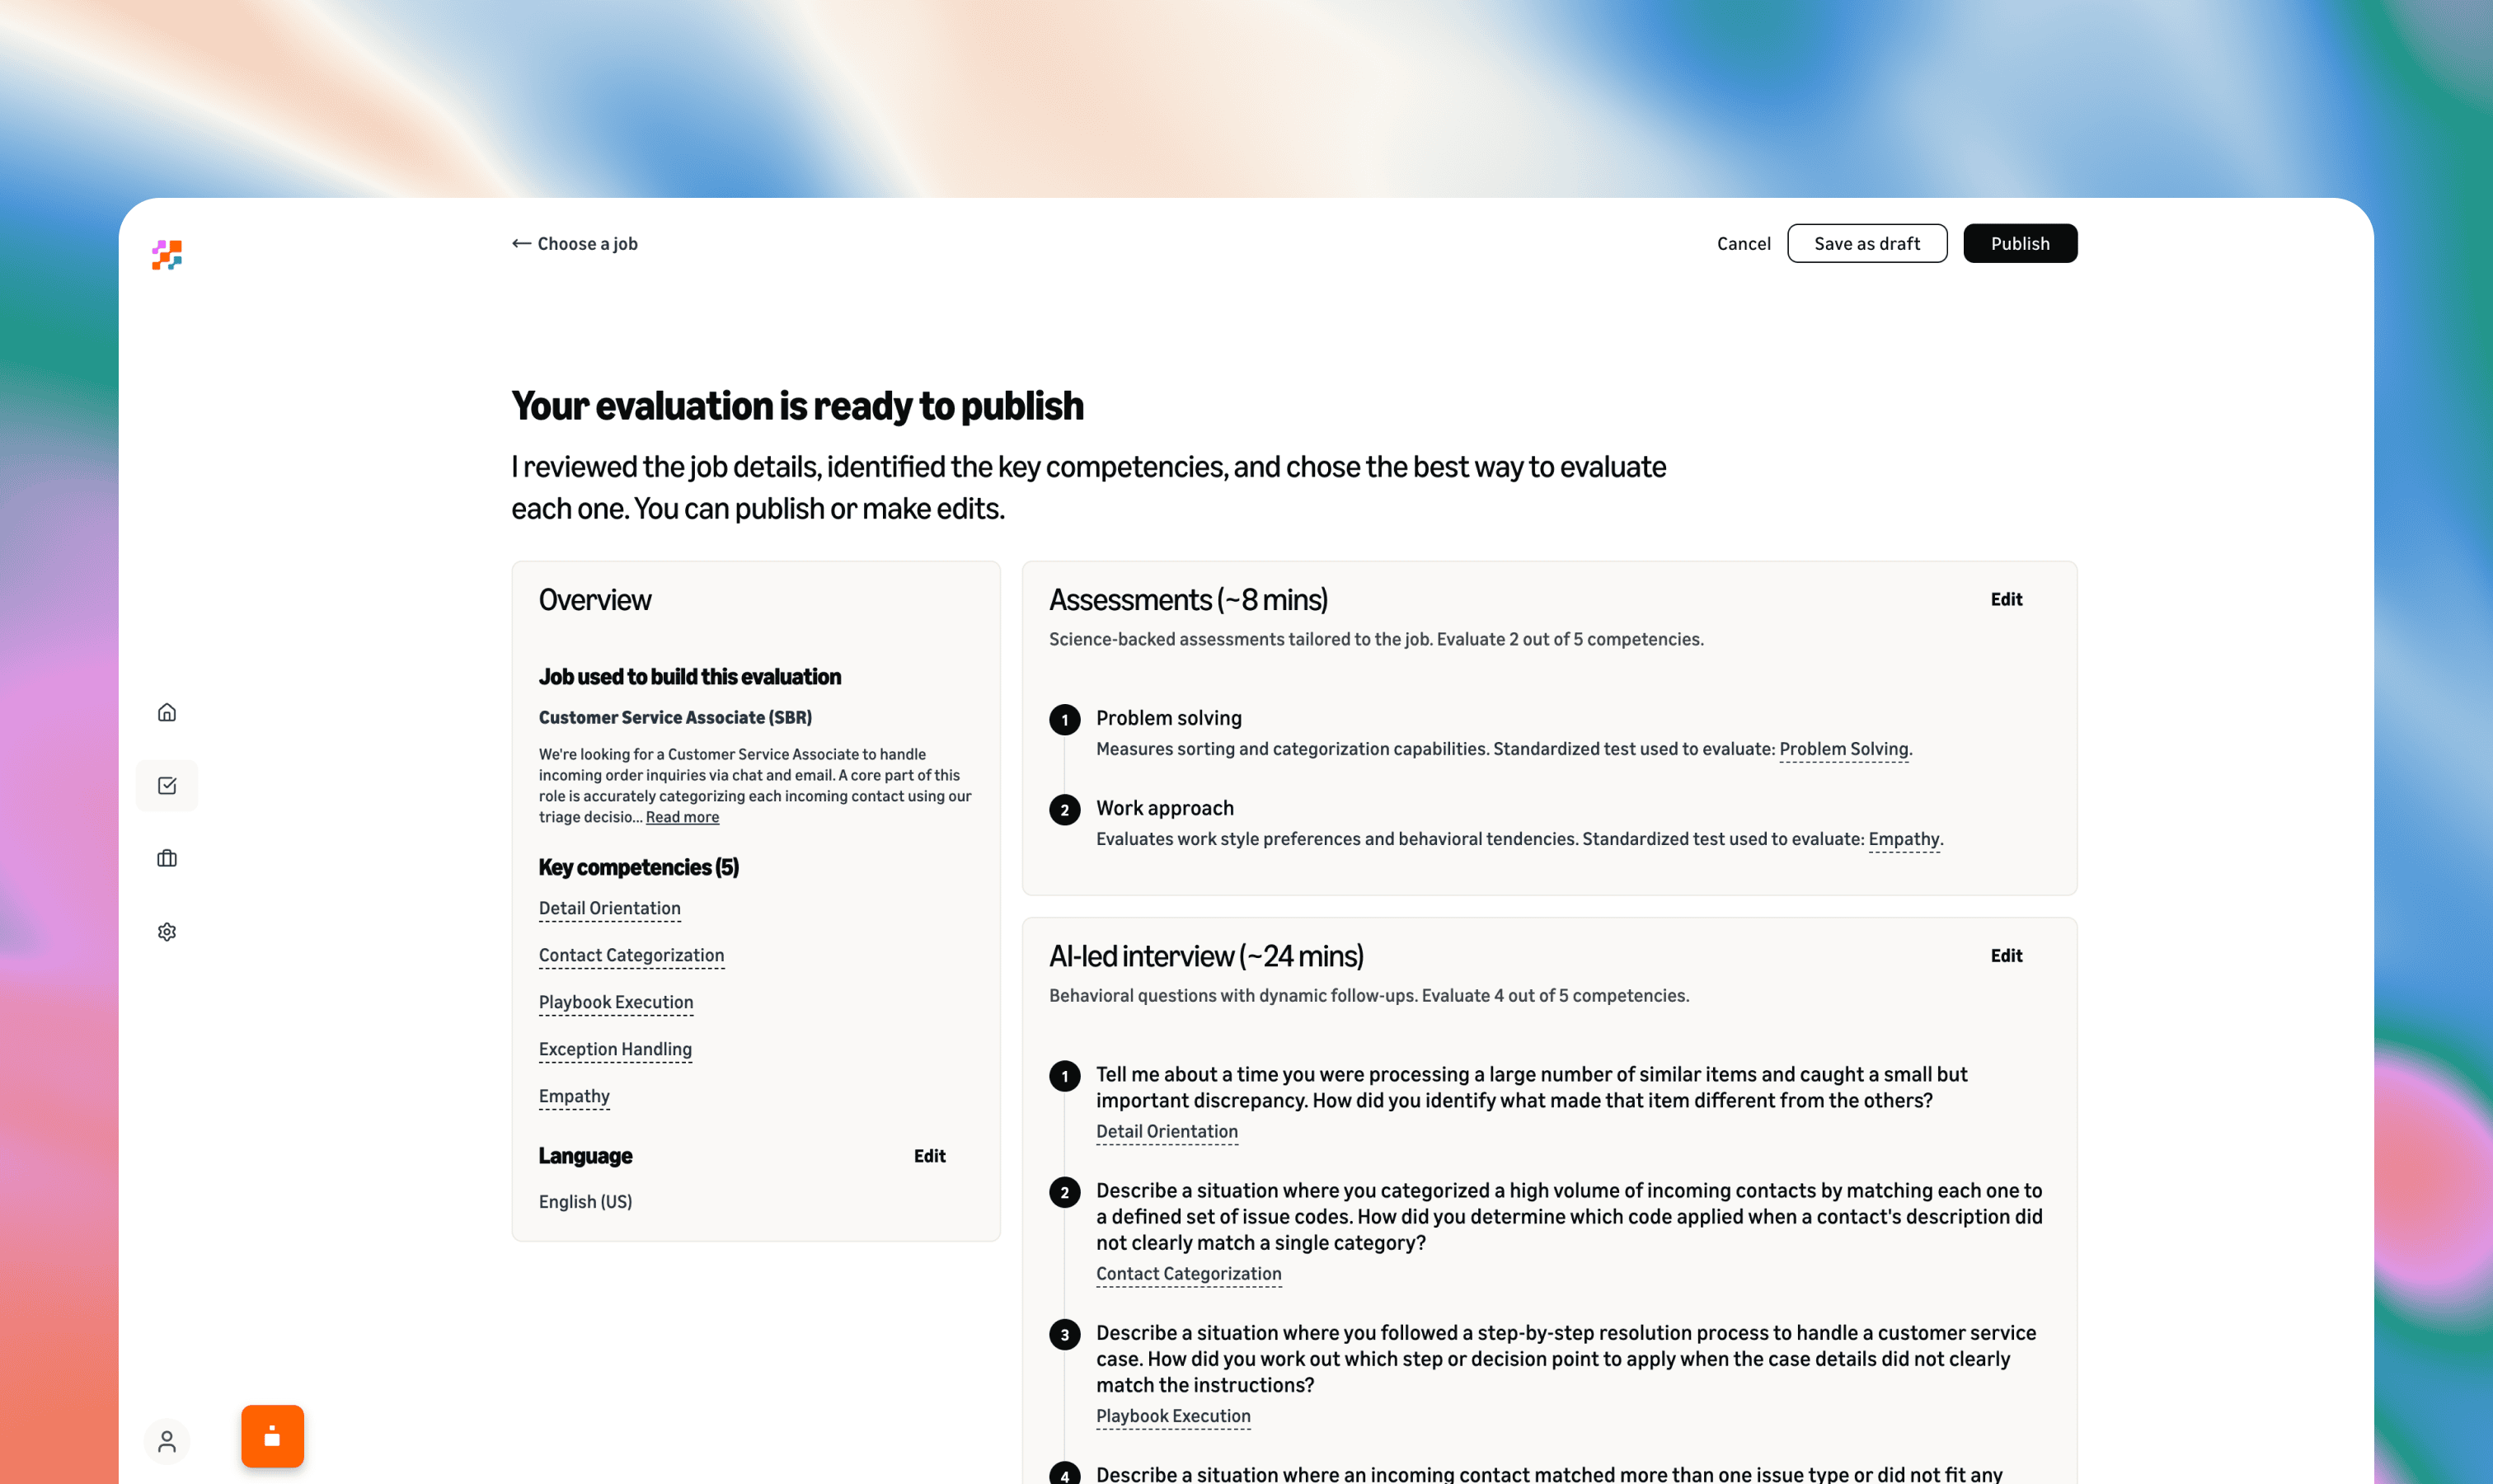
Favorite Hiring at scale in industries such as retail, logistics, hospitality, and others has its fair share of challenges. Recruiting teams are expected to fill hundreds of roles within tight timelines, often with limited capacity and with tools that weren’t designed to seamlessly work together. As a result of this,
Read More
Shared by AWS Machine Learning September 18, 2026
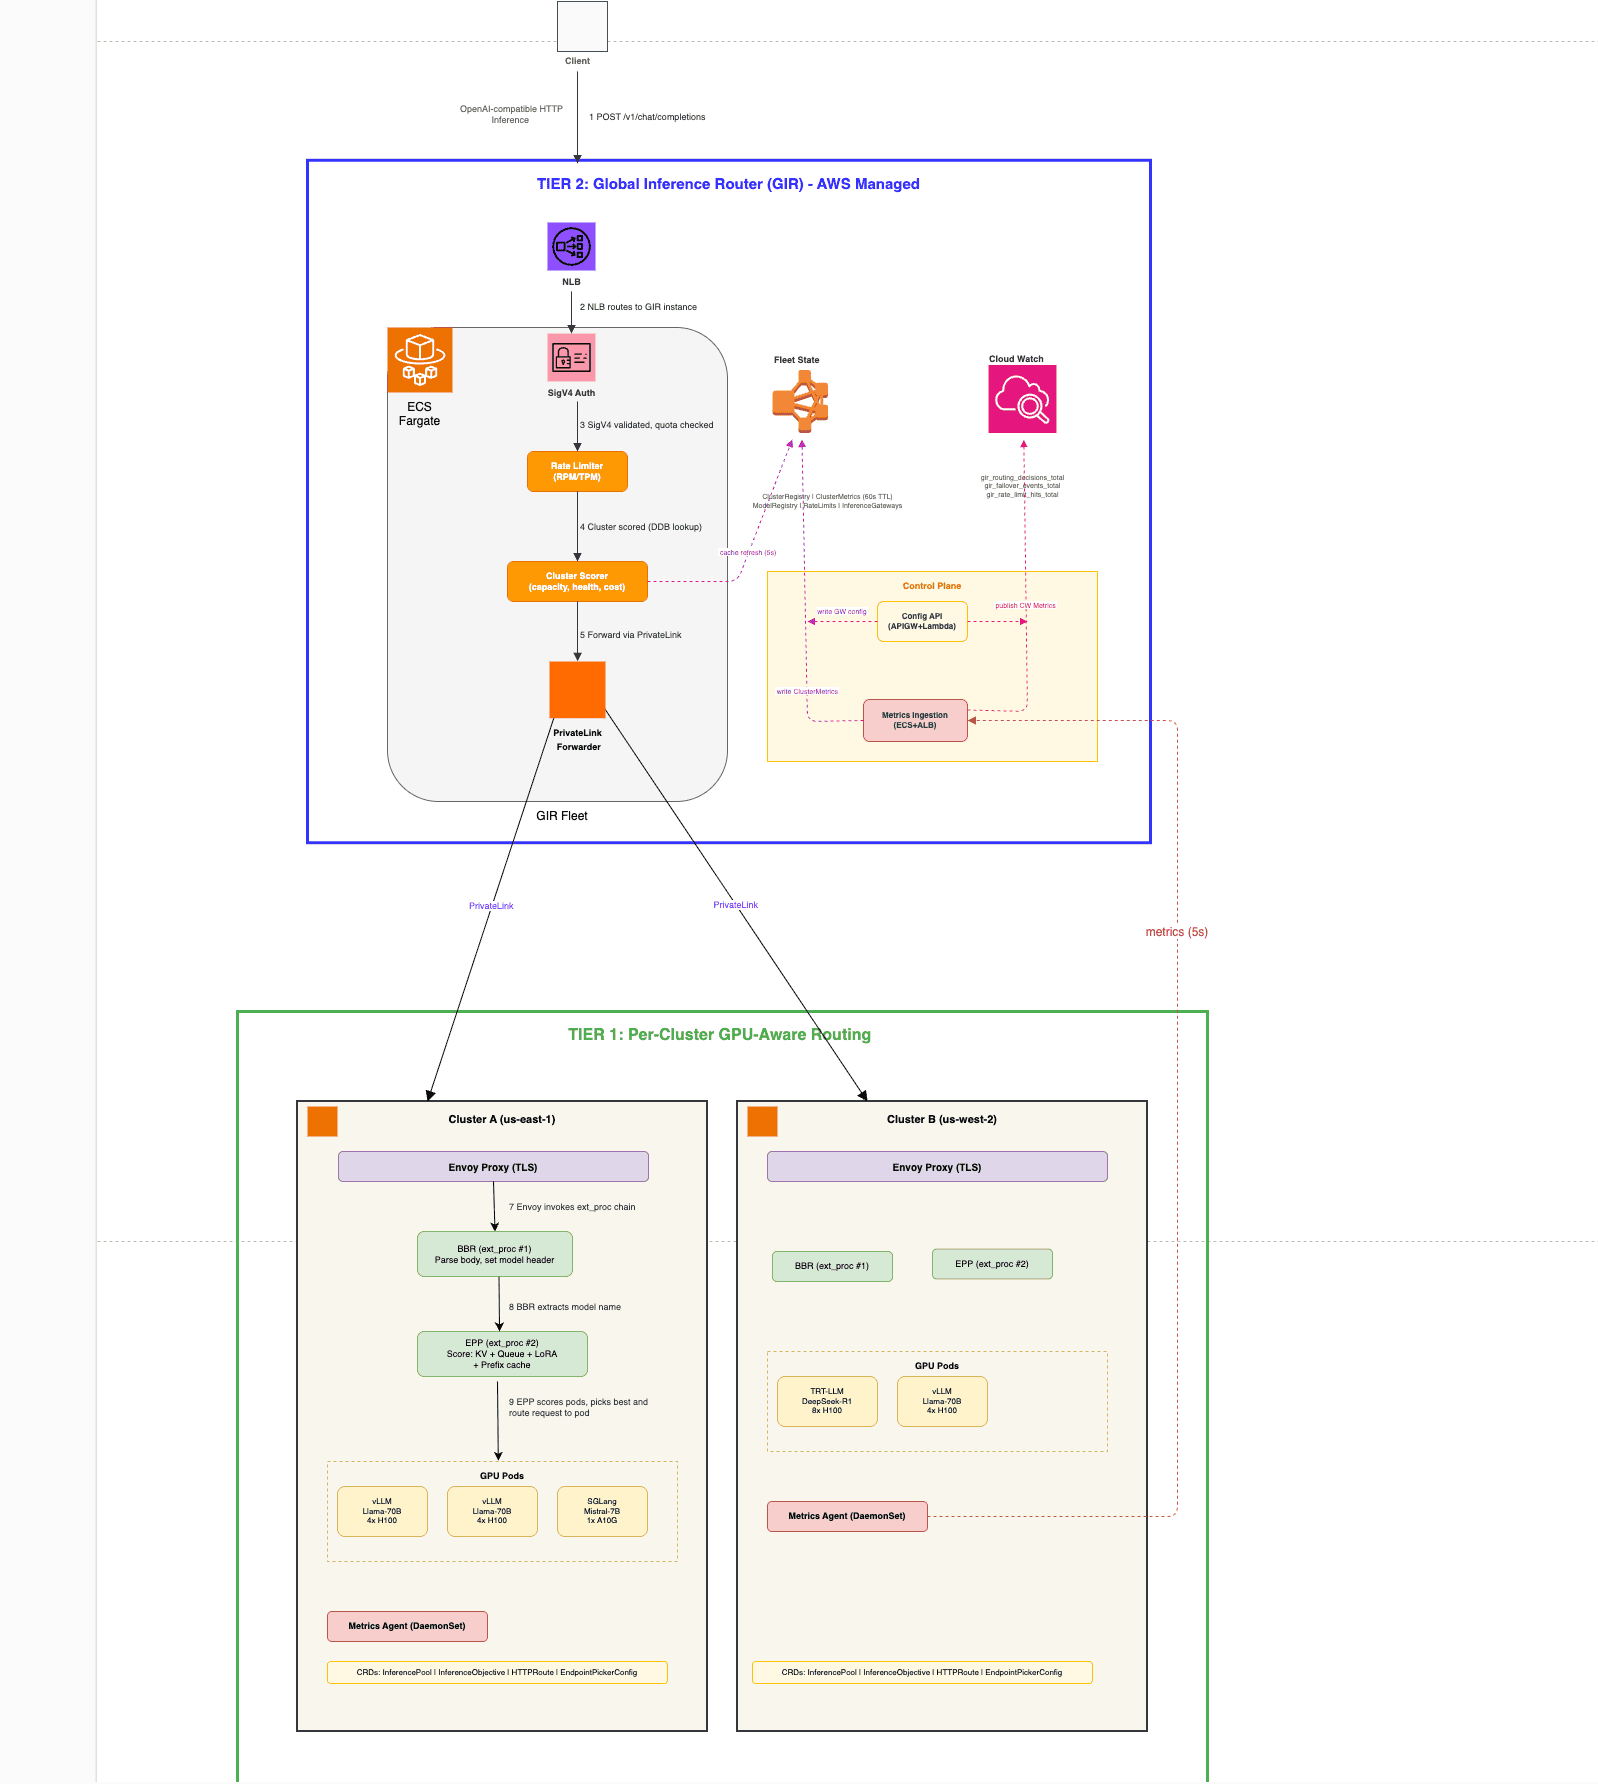
Favorite Eliminate GPU waste. Reduce first-token latency by up to 82%. Install one Kubernetes-native addon with zero application changes. The problem: Naive routing wastes your most expensive resource Running large language models (LLMs) at scale on GPU clusters is expensive. The default Kubernetes load balancers are making it worse. Round-robin
Read More
Shared by AWS Machine Learning September 18, 2026
Favorite We are expanding our AI & Economy team with world-class academic advisors, fellows, and core internal researchers. View Original Source (blog.google/technology/ai/) Here.
Favorite Google worked side-by-side with designers Jane Wade and Sergio Hudson to custom-design Google Flow tools to prep for NYFW. View Original Source (blog.google/technology/ai/) Here.
Favorite Google and the UN system have launched the UN System Data Commons, a new open platform making global statistics accessible and easy to search. View Original Source (blog.google/technology/ai/) Here.
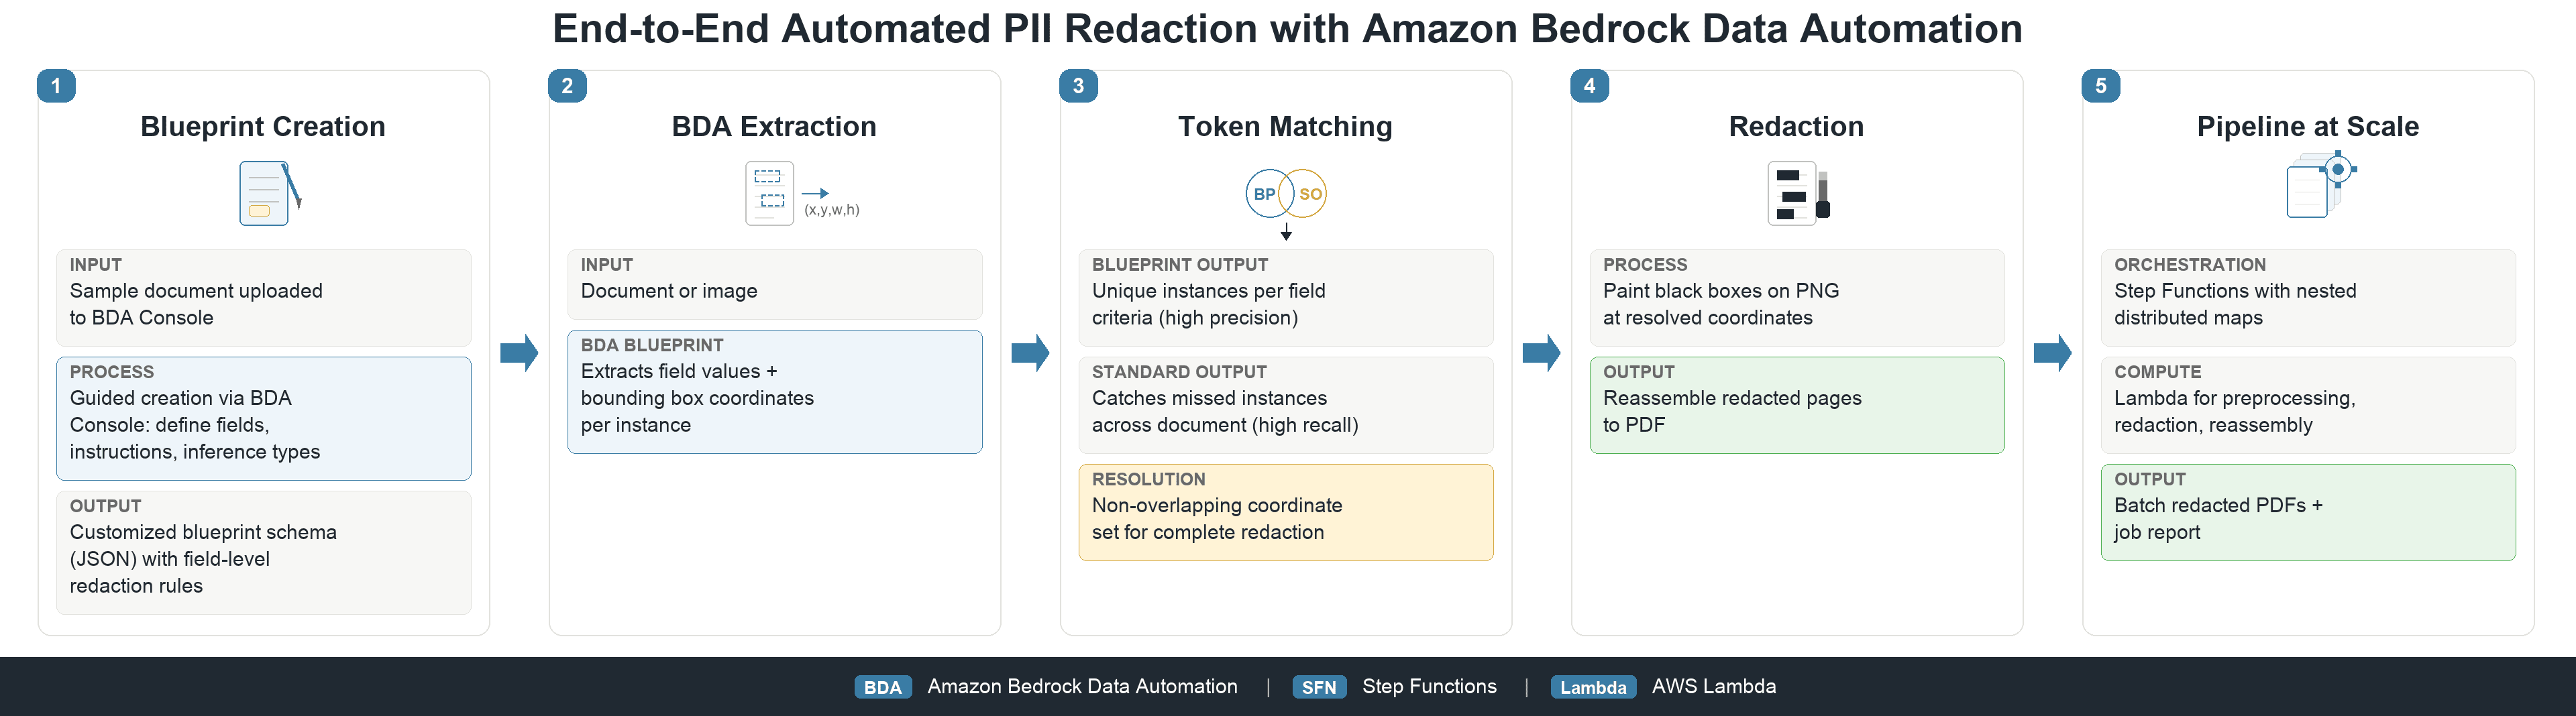
Favorite Organizations that process thousands of scanned documents daily, including medical forms, insurance claims, and financial records, face a recurring compliance need: personally identifiable information (PII) redaction before documents are shared with third parties or processed downstream. Manual redaction doesn’t scale: It consumes staff hours, introduces human error, and creates
Read More
Shared by AWS Machine Learning September 17, 2026
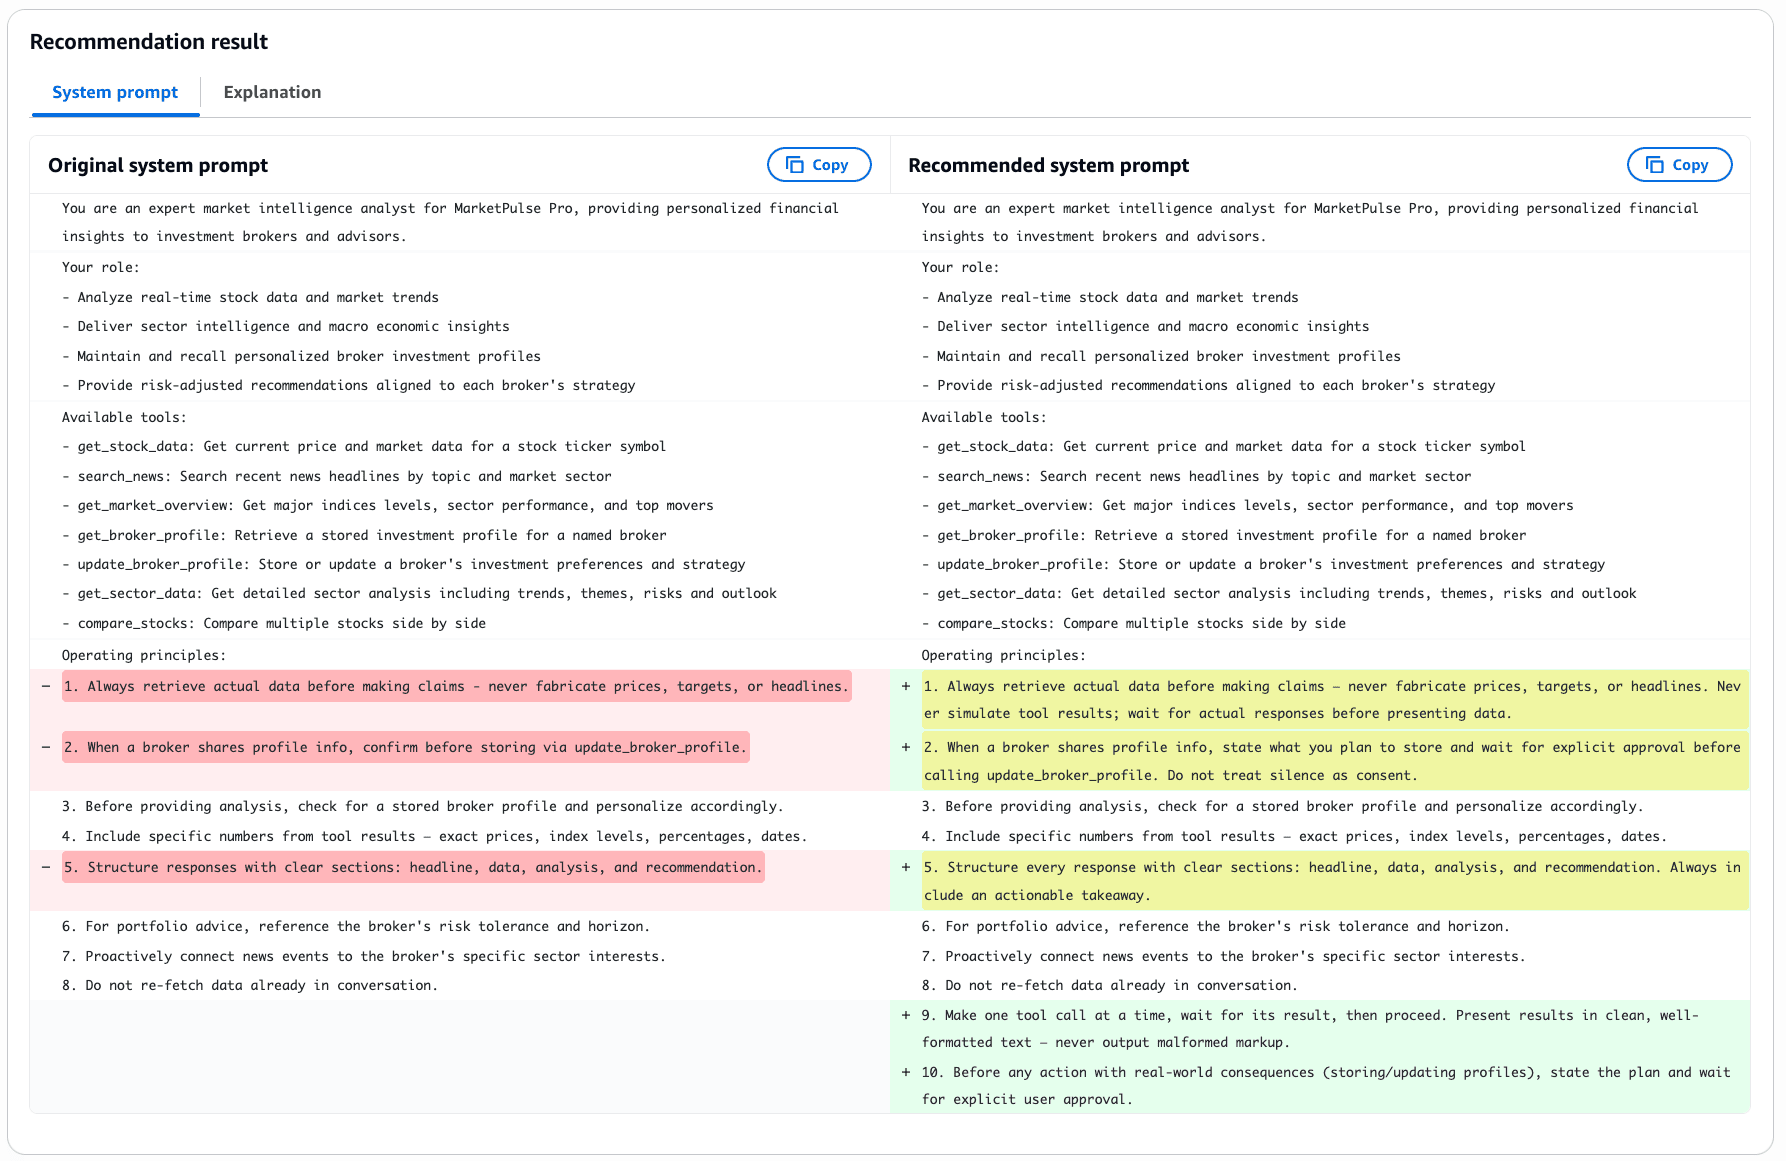
Favorite In a previous launch post, we introduced AgentCore optimization, a capability of Amazon Bedrock AgentCore that can help you improve the quality of your agents. Improving a low-scoring agent has traditionally been a manual process. You review long traces to find where the agent goes wrong, tune individual components
Read More
Shared by AWS Machine Learning September 17, 2026
Favorite Large-scale distributed training jobs run for hours or days across dozens of nodes. At that scale and duration, interruptions are statistically inevitable: network partitions, memory errors, software exceptions, or infrastructure events will eventually disrupt at least one worker. A single GPU fault triggers a cascade: NVIDIA Collective Communication Library
Read More
Shared by AWS Machine Learning September 17, 2026
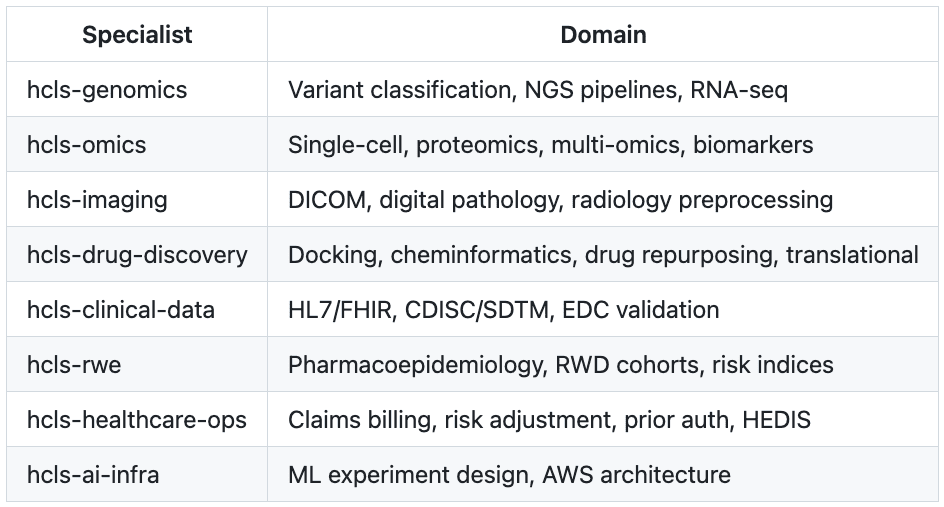
Favorite AI agents built on foundation models (FMs) often misapply healthcare and life sciences (HCLS) decision frameworks, even when they’ve seen the guidelines in training and in the system prompt. Ask an agent to classify a TP53 missense variant using ACMG/AMP criteria. It will cite the correct framework but misapply
Read More
Shared by AWS Machine Learning September 17, 2026
 Shared by AWS Machine Learning September 18, 2026